Foundation
The governed foundation beneath every agent.
HUMAIN Fabric turns fragmented enterprise data into governed, AI-ready systems in minutes, not weeks.
FoundationThe governed foundation beneath every agent.
IntelligenceAgents built into every module.
 Consult
Production AI starts with the right foundation.
 works across industries

Agentic ERP for ministries, smart-city dashboards, and citizen-services automation.

Arabic medical NLP, clinical data lakes, patient-record governance, and drug-interaction RAG.

Predictive-maintenance pipelines, sensor-data ingestion, and Aramco-grade data sovereignty.

Fraud-detection models, Arabic-language compliance, and real-time transaction analytics.

Arabic content enrichment, subtitle generation, and SBA content-partnership pipelines.

K-12 EdTech data platforms, university research compute, and Arabic corpus curation.
Fragmented data is the real barrier to AI
Your data lives in fragmented silos: disconnected pipelines, inconsistent labels, no governance, no lineage. Agents cannot act safely on top of it.
Sources are unified, pipelines auto-generate, governance and lineage are enforced by default, and agents can retrieve, reason, and act on the data instantly, fully auditable.
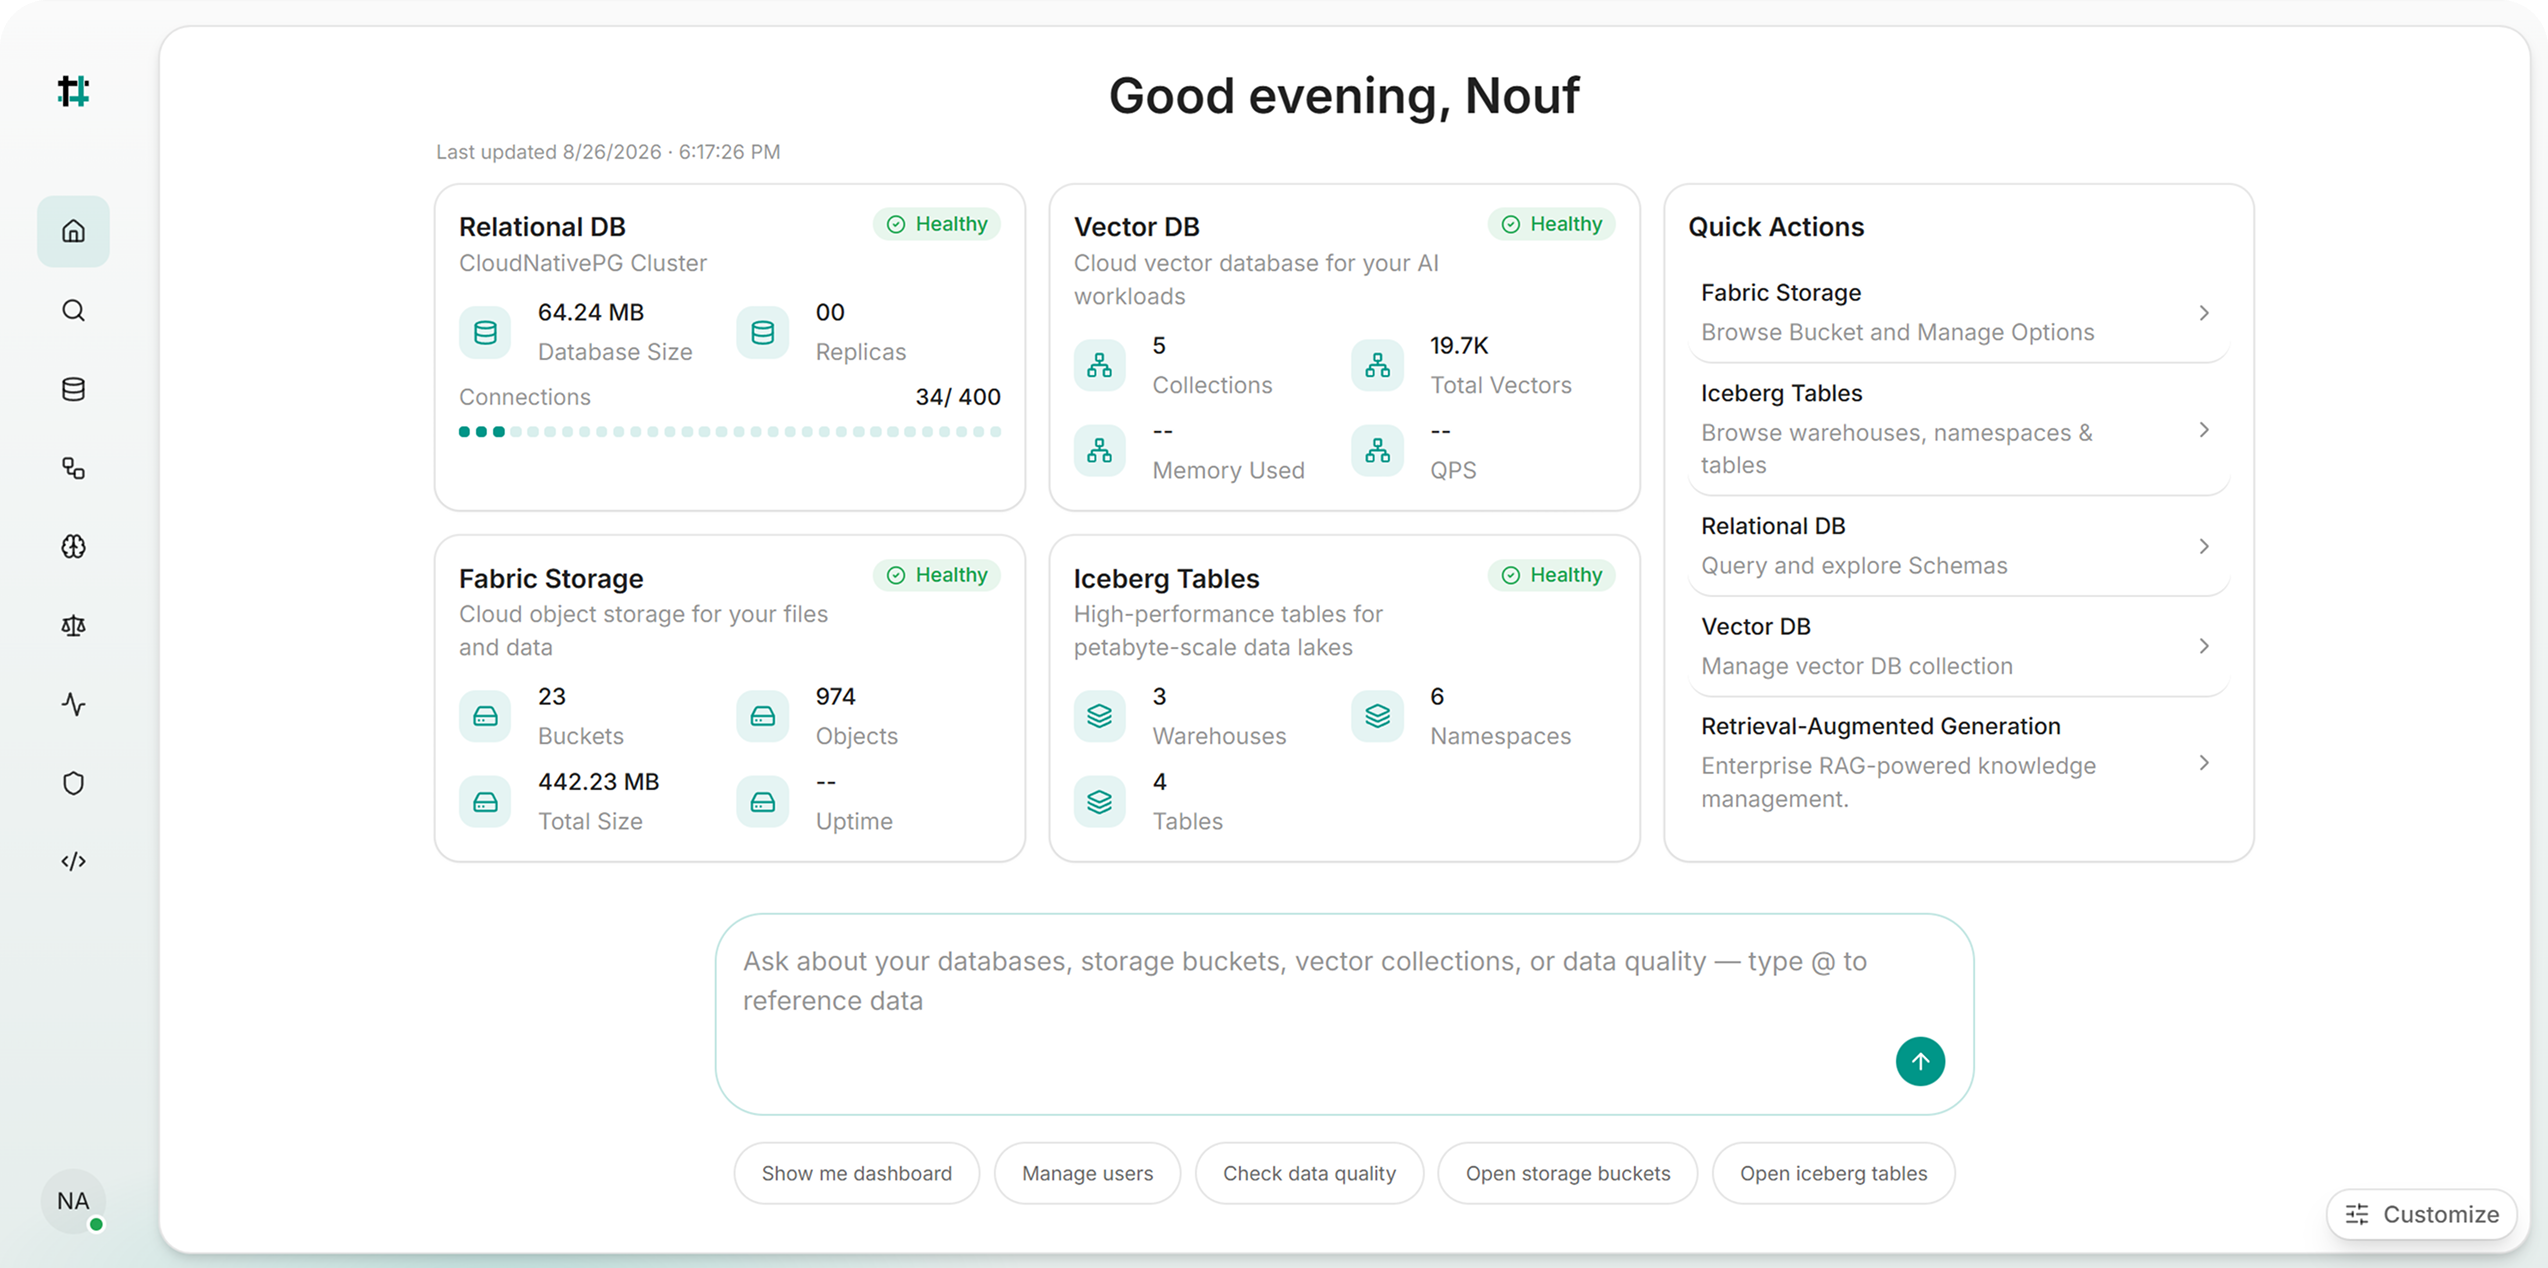
HUMAIN Fabric is an AI-native data platform that ingests, processes, governs, and prepares enterprise data so AI agents can retrieve, reason, and act with full lineage and control.
HUMAIN Fabric is built for regulated enterprises across government, healthcare, financial services, energy, media, and education.
Fabric Foundation connects, stores, processes, catalogs, and governs enterprise data, creating a trusted foundation for AI.
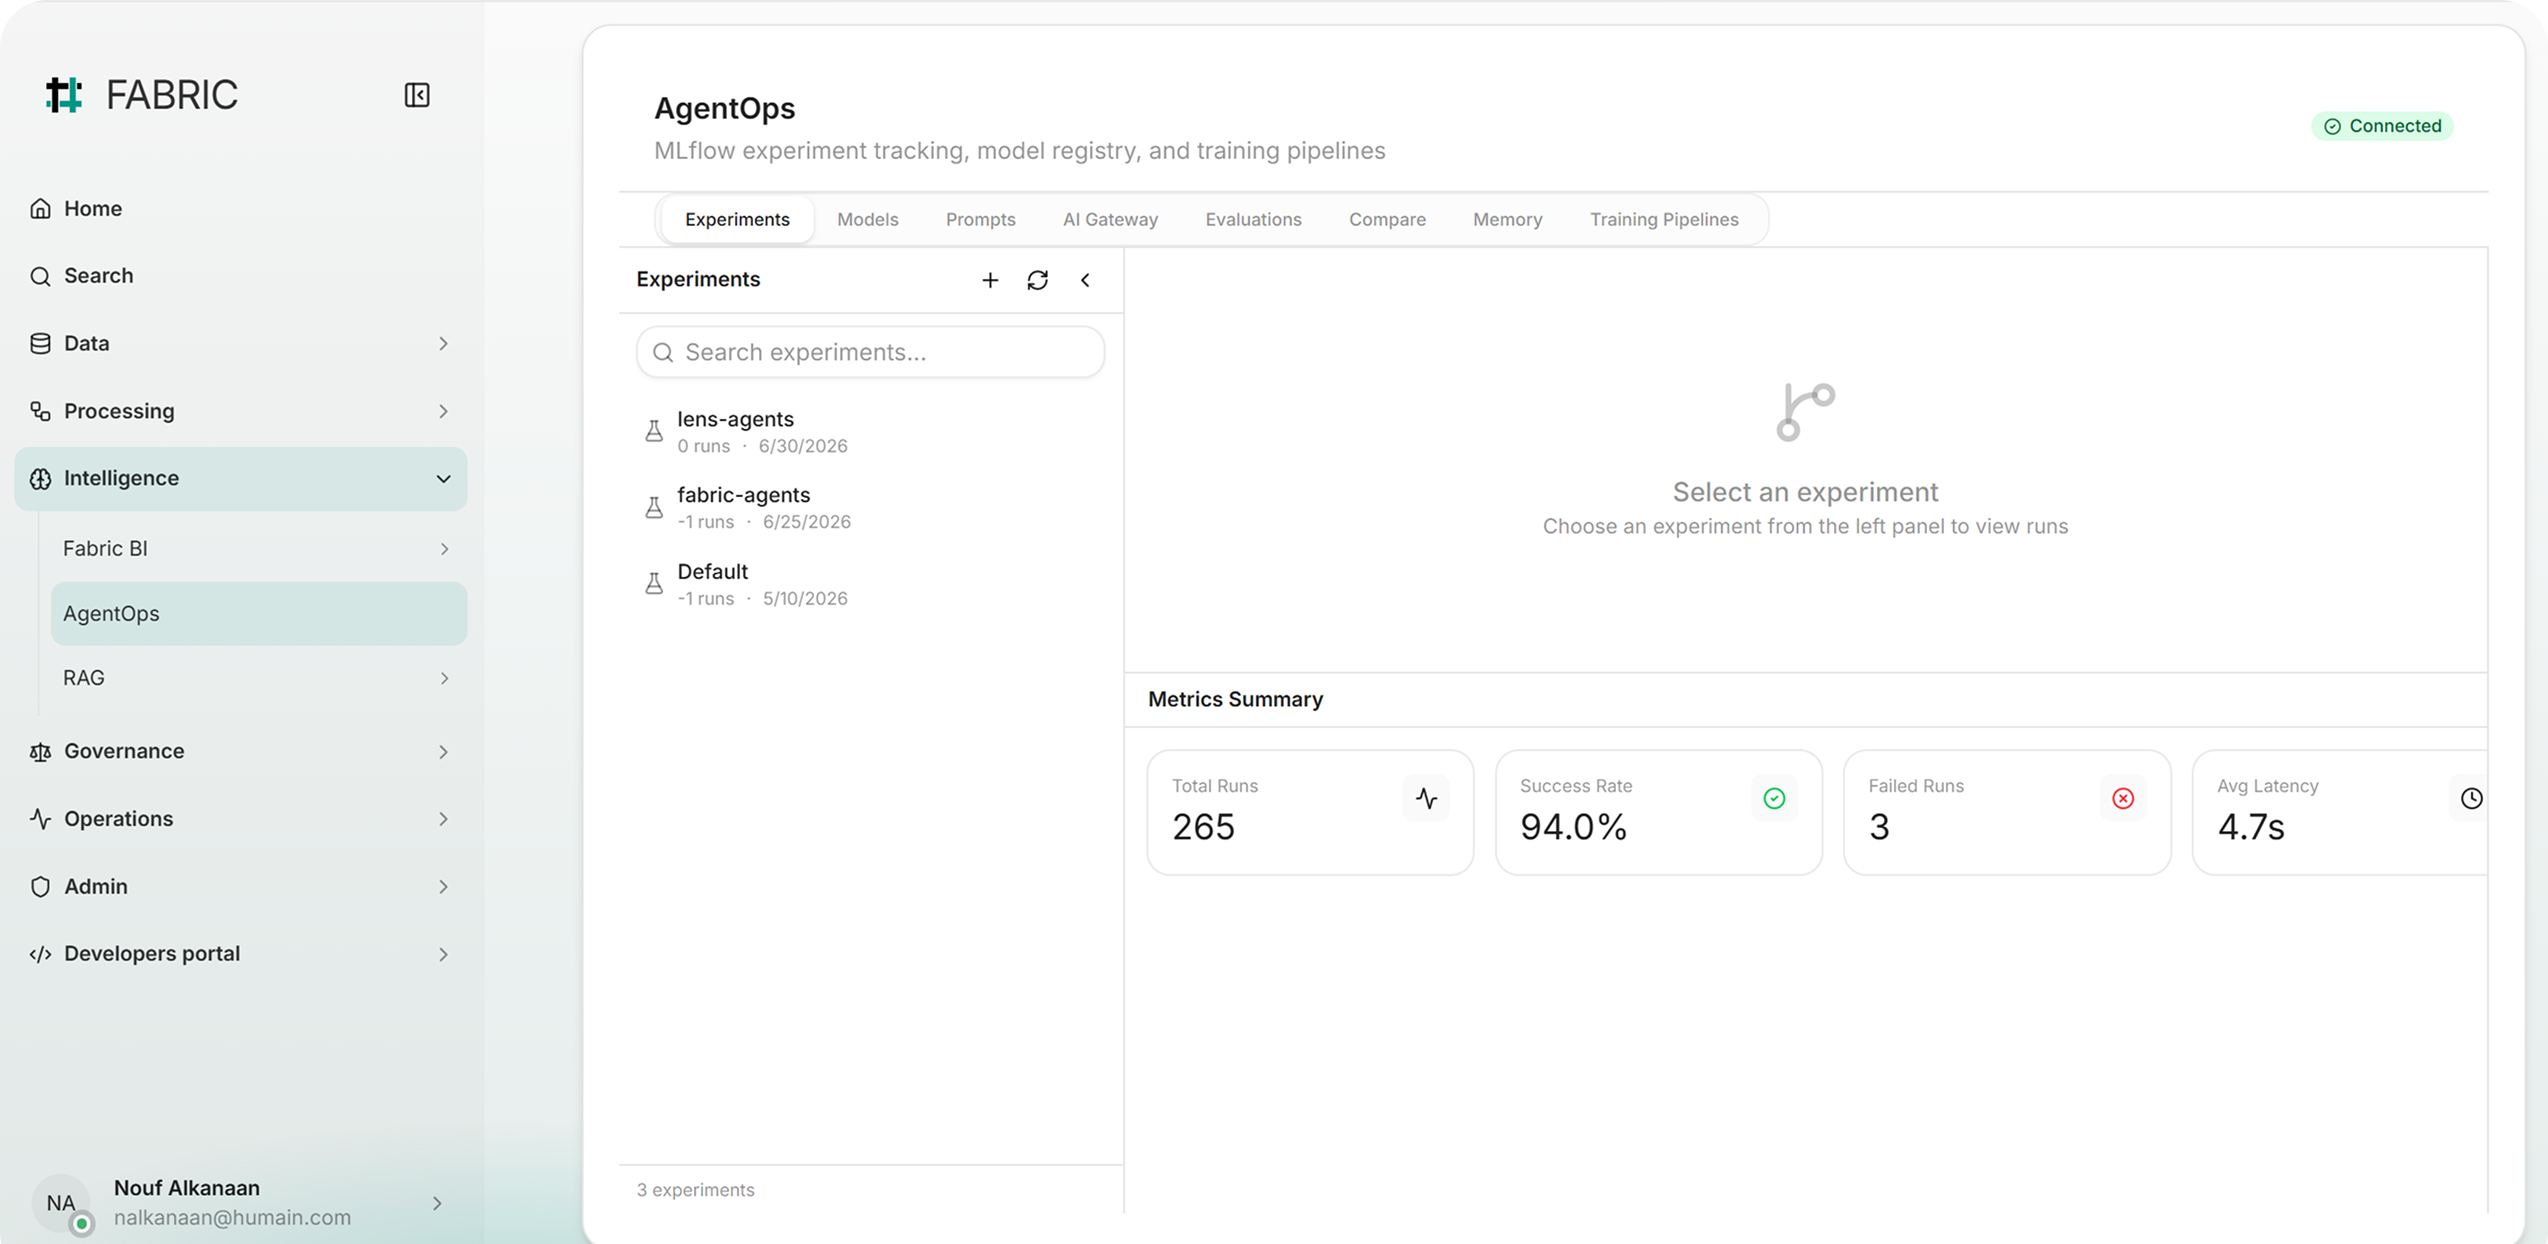
Fabric Intelligence lets you interact with enterprise data through AI agents, conversational retrieval, and self-service analytics.
Explore the interactive platform experience, talk to our team, or engage Fabric Consult to move from AI readiness to production.
HUMAIN Fabric streamlines onboarding by unifying data sources, auto-generating pipelines, and providing a ready-to-use analytics stack so production data work can begin in minutes, not weeks.
Demo video coming soon.
Fabric Foundation ingests, stores, processes, catalogs, and governs enterprise data, so the intelligence layer can operate on it safely. End to end, from ingestion to insight.
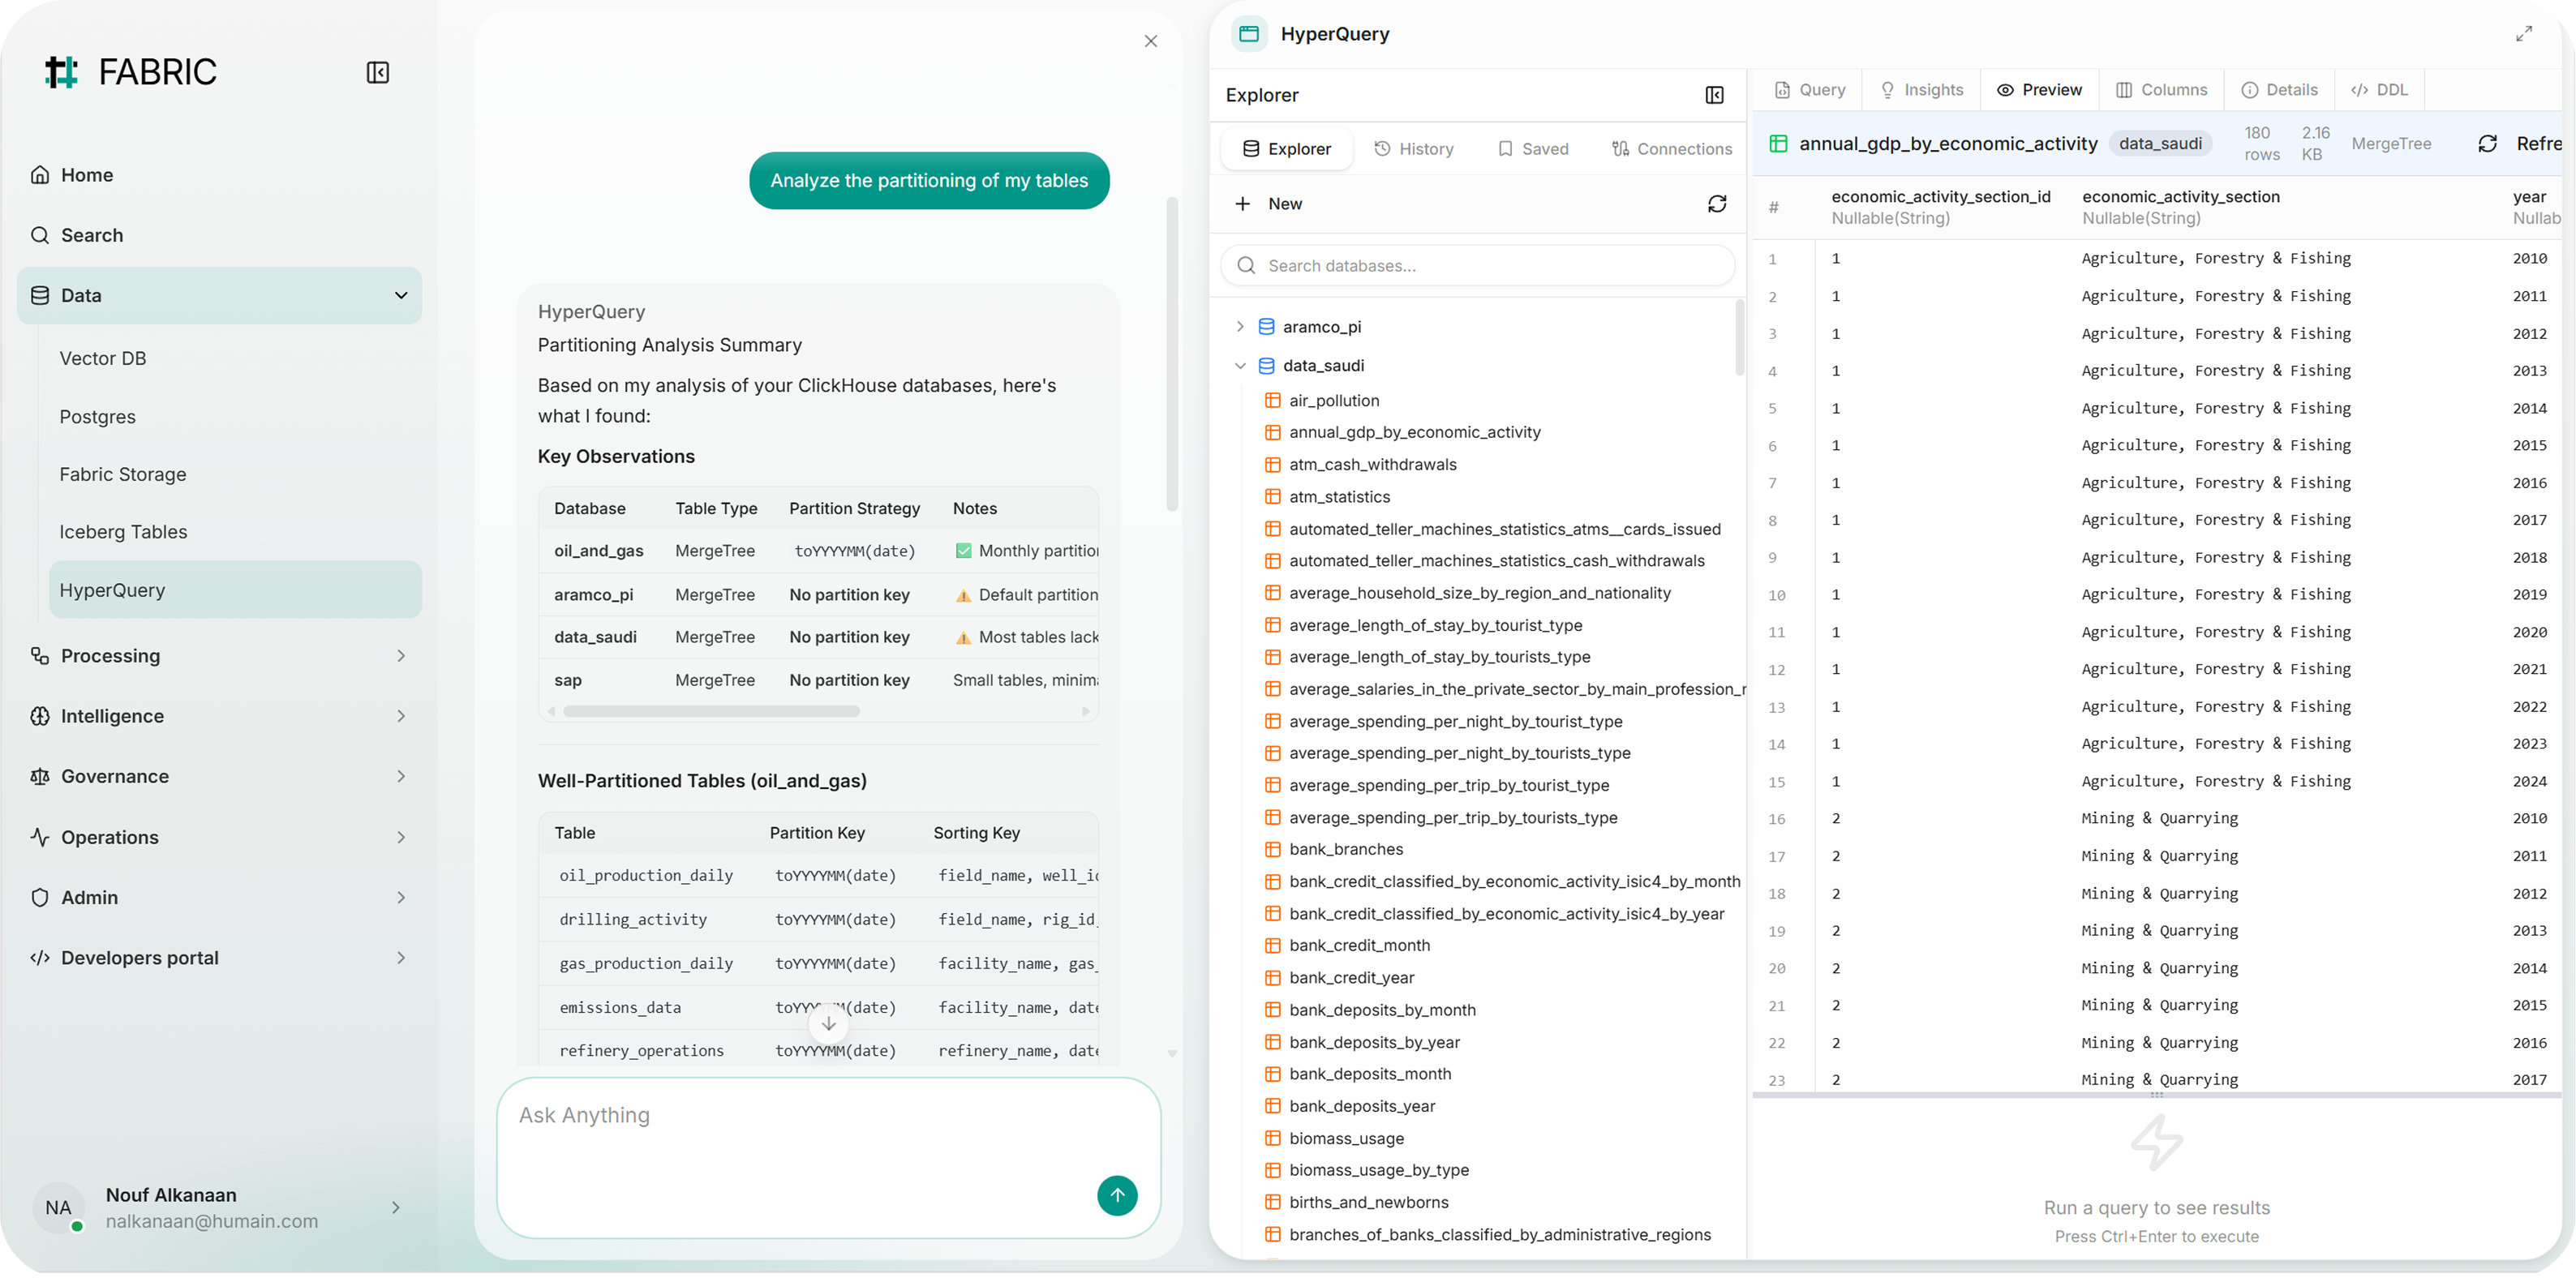
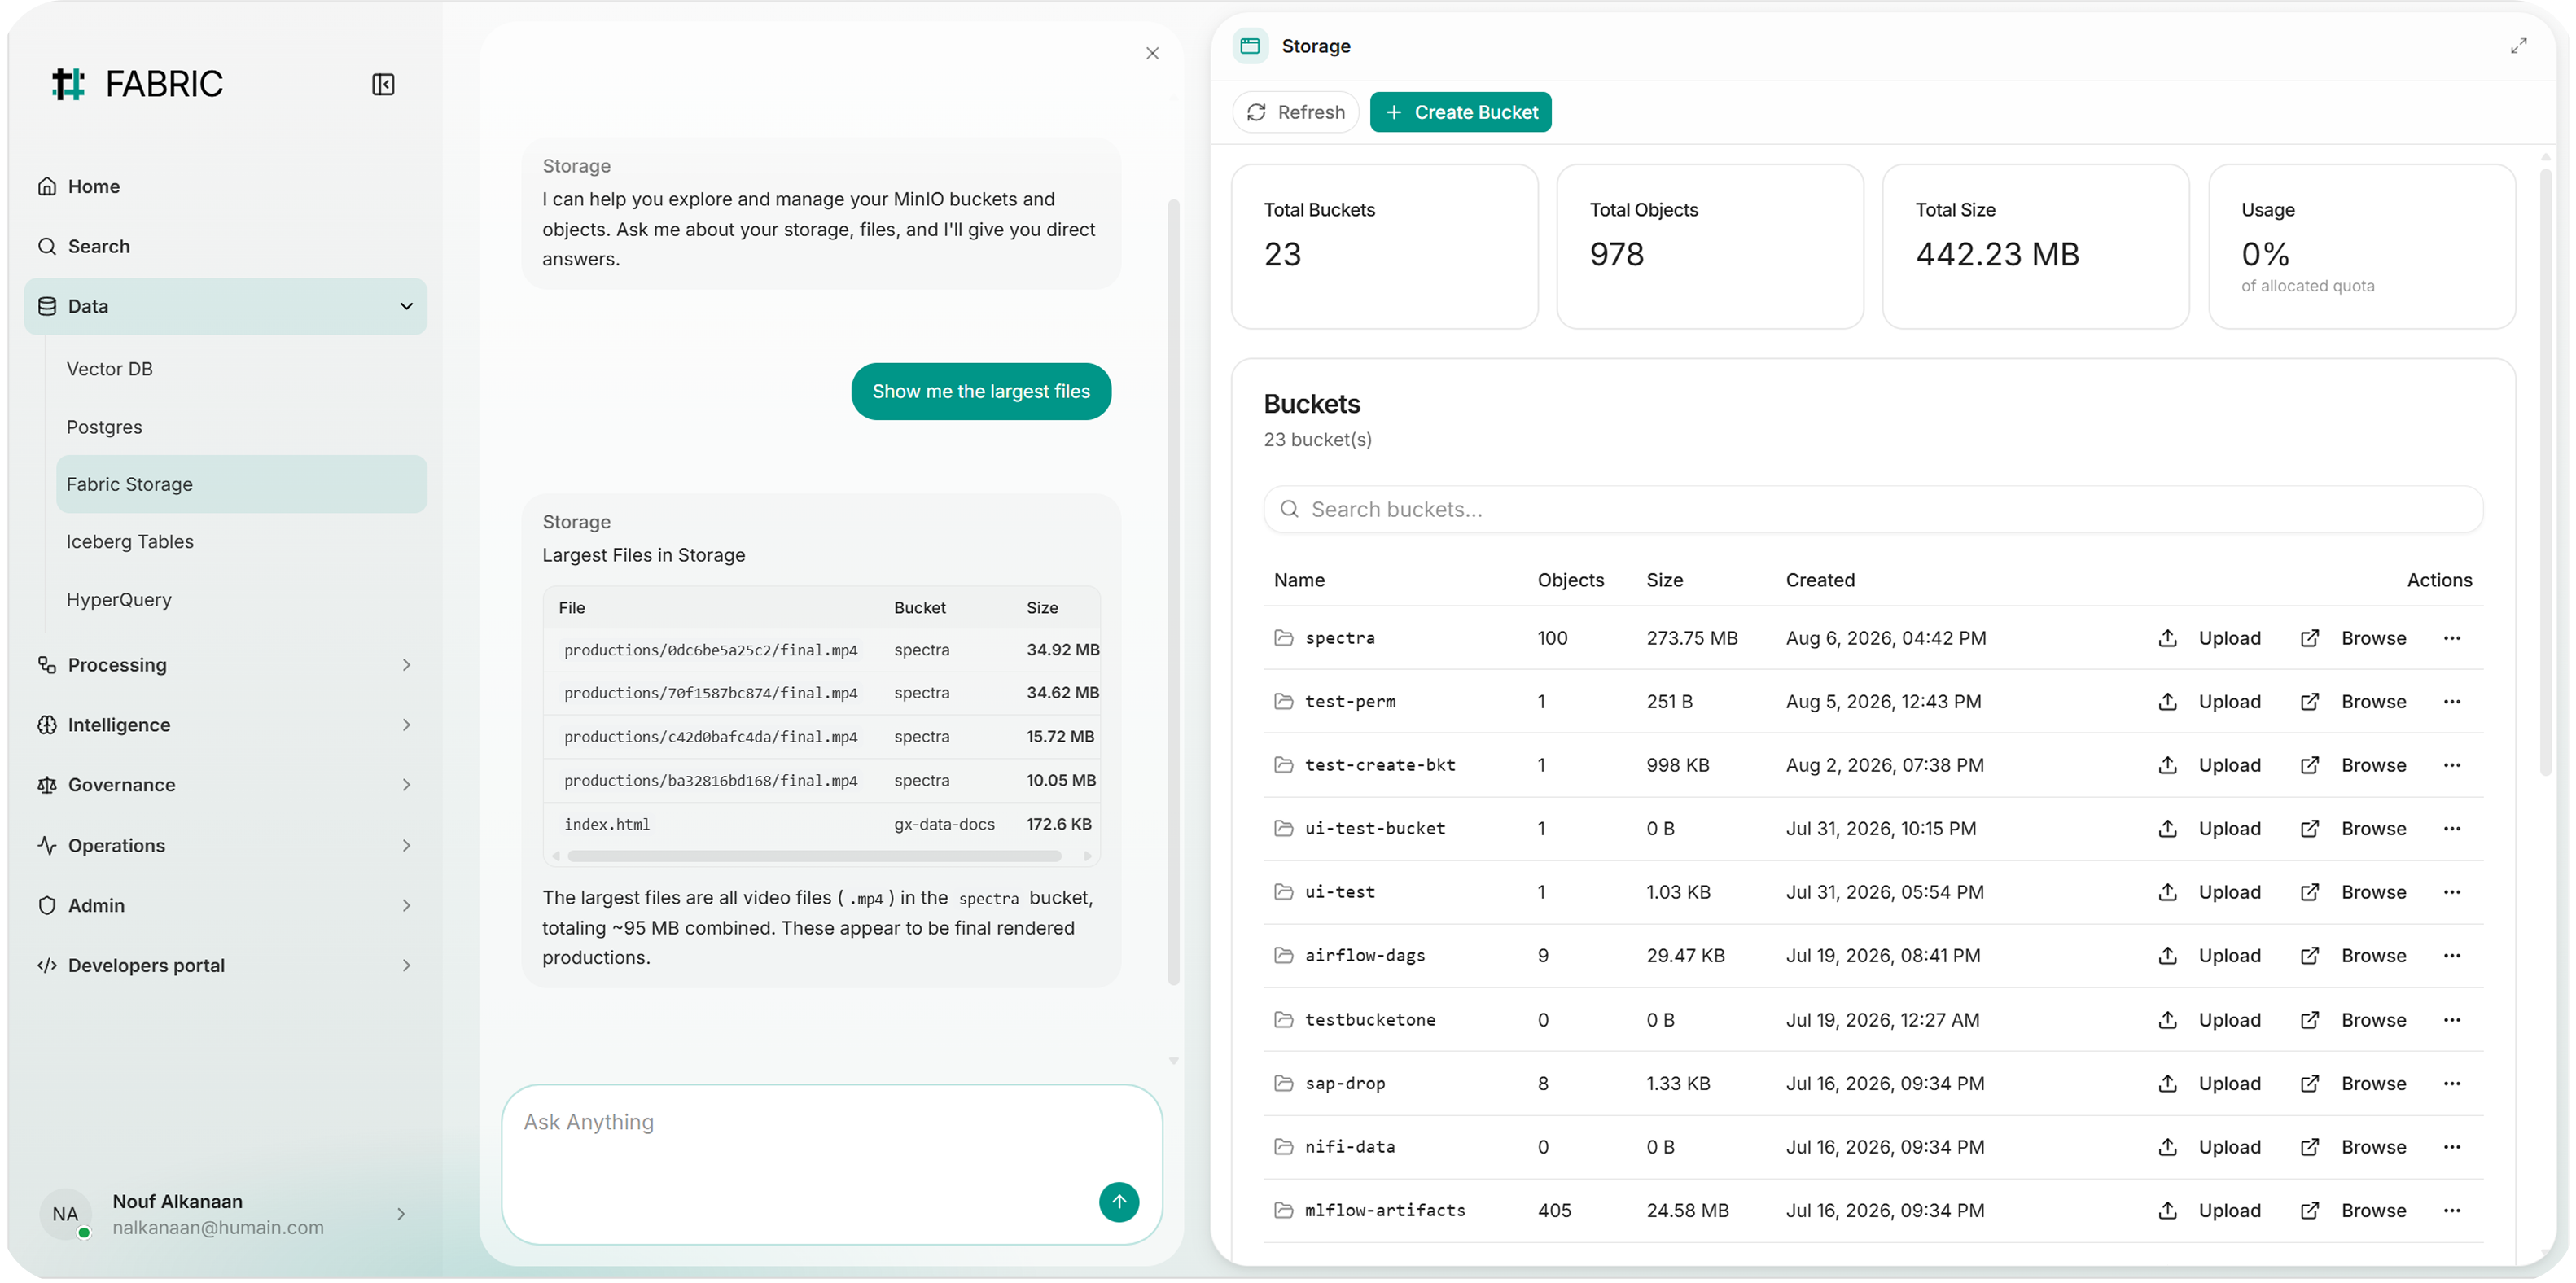
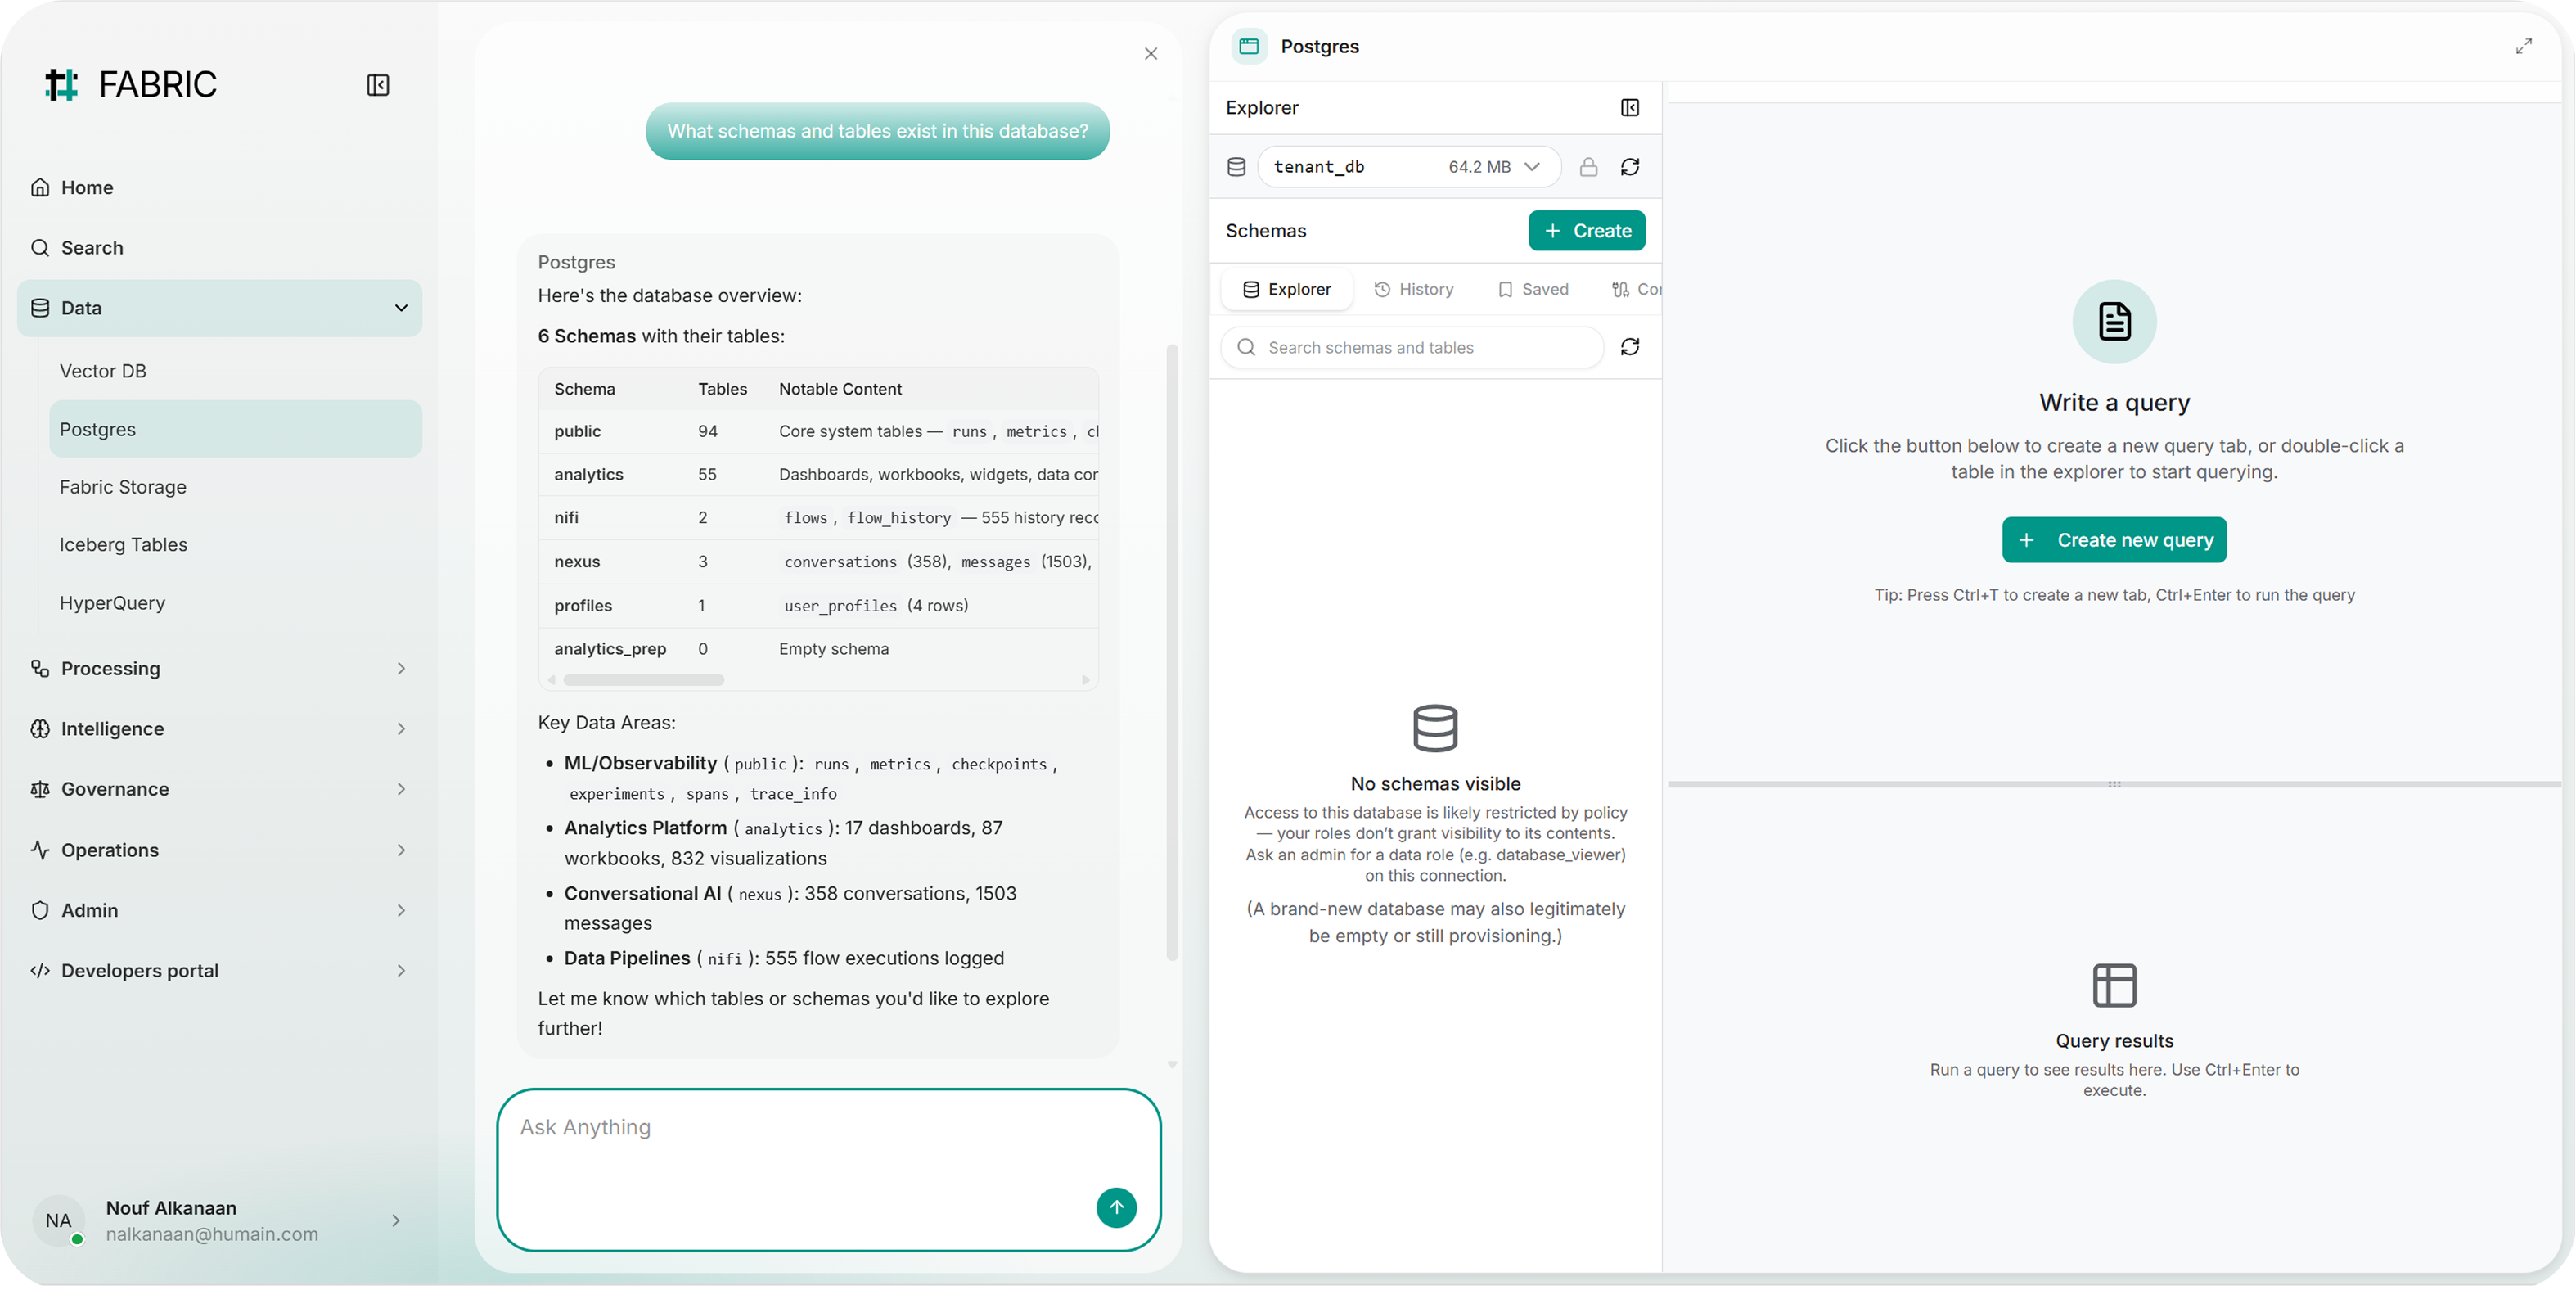
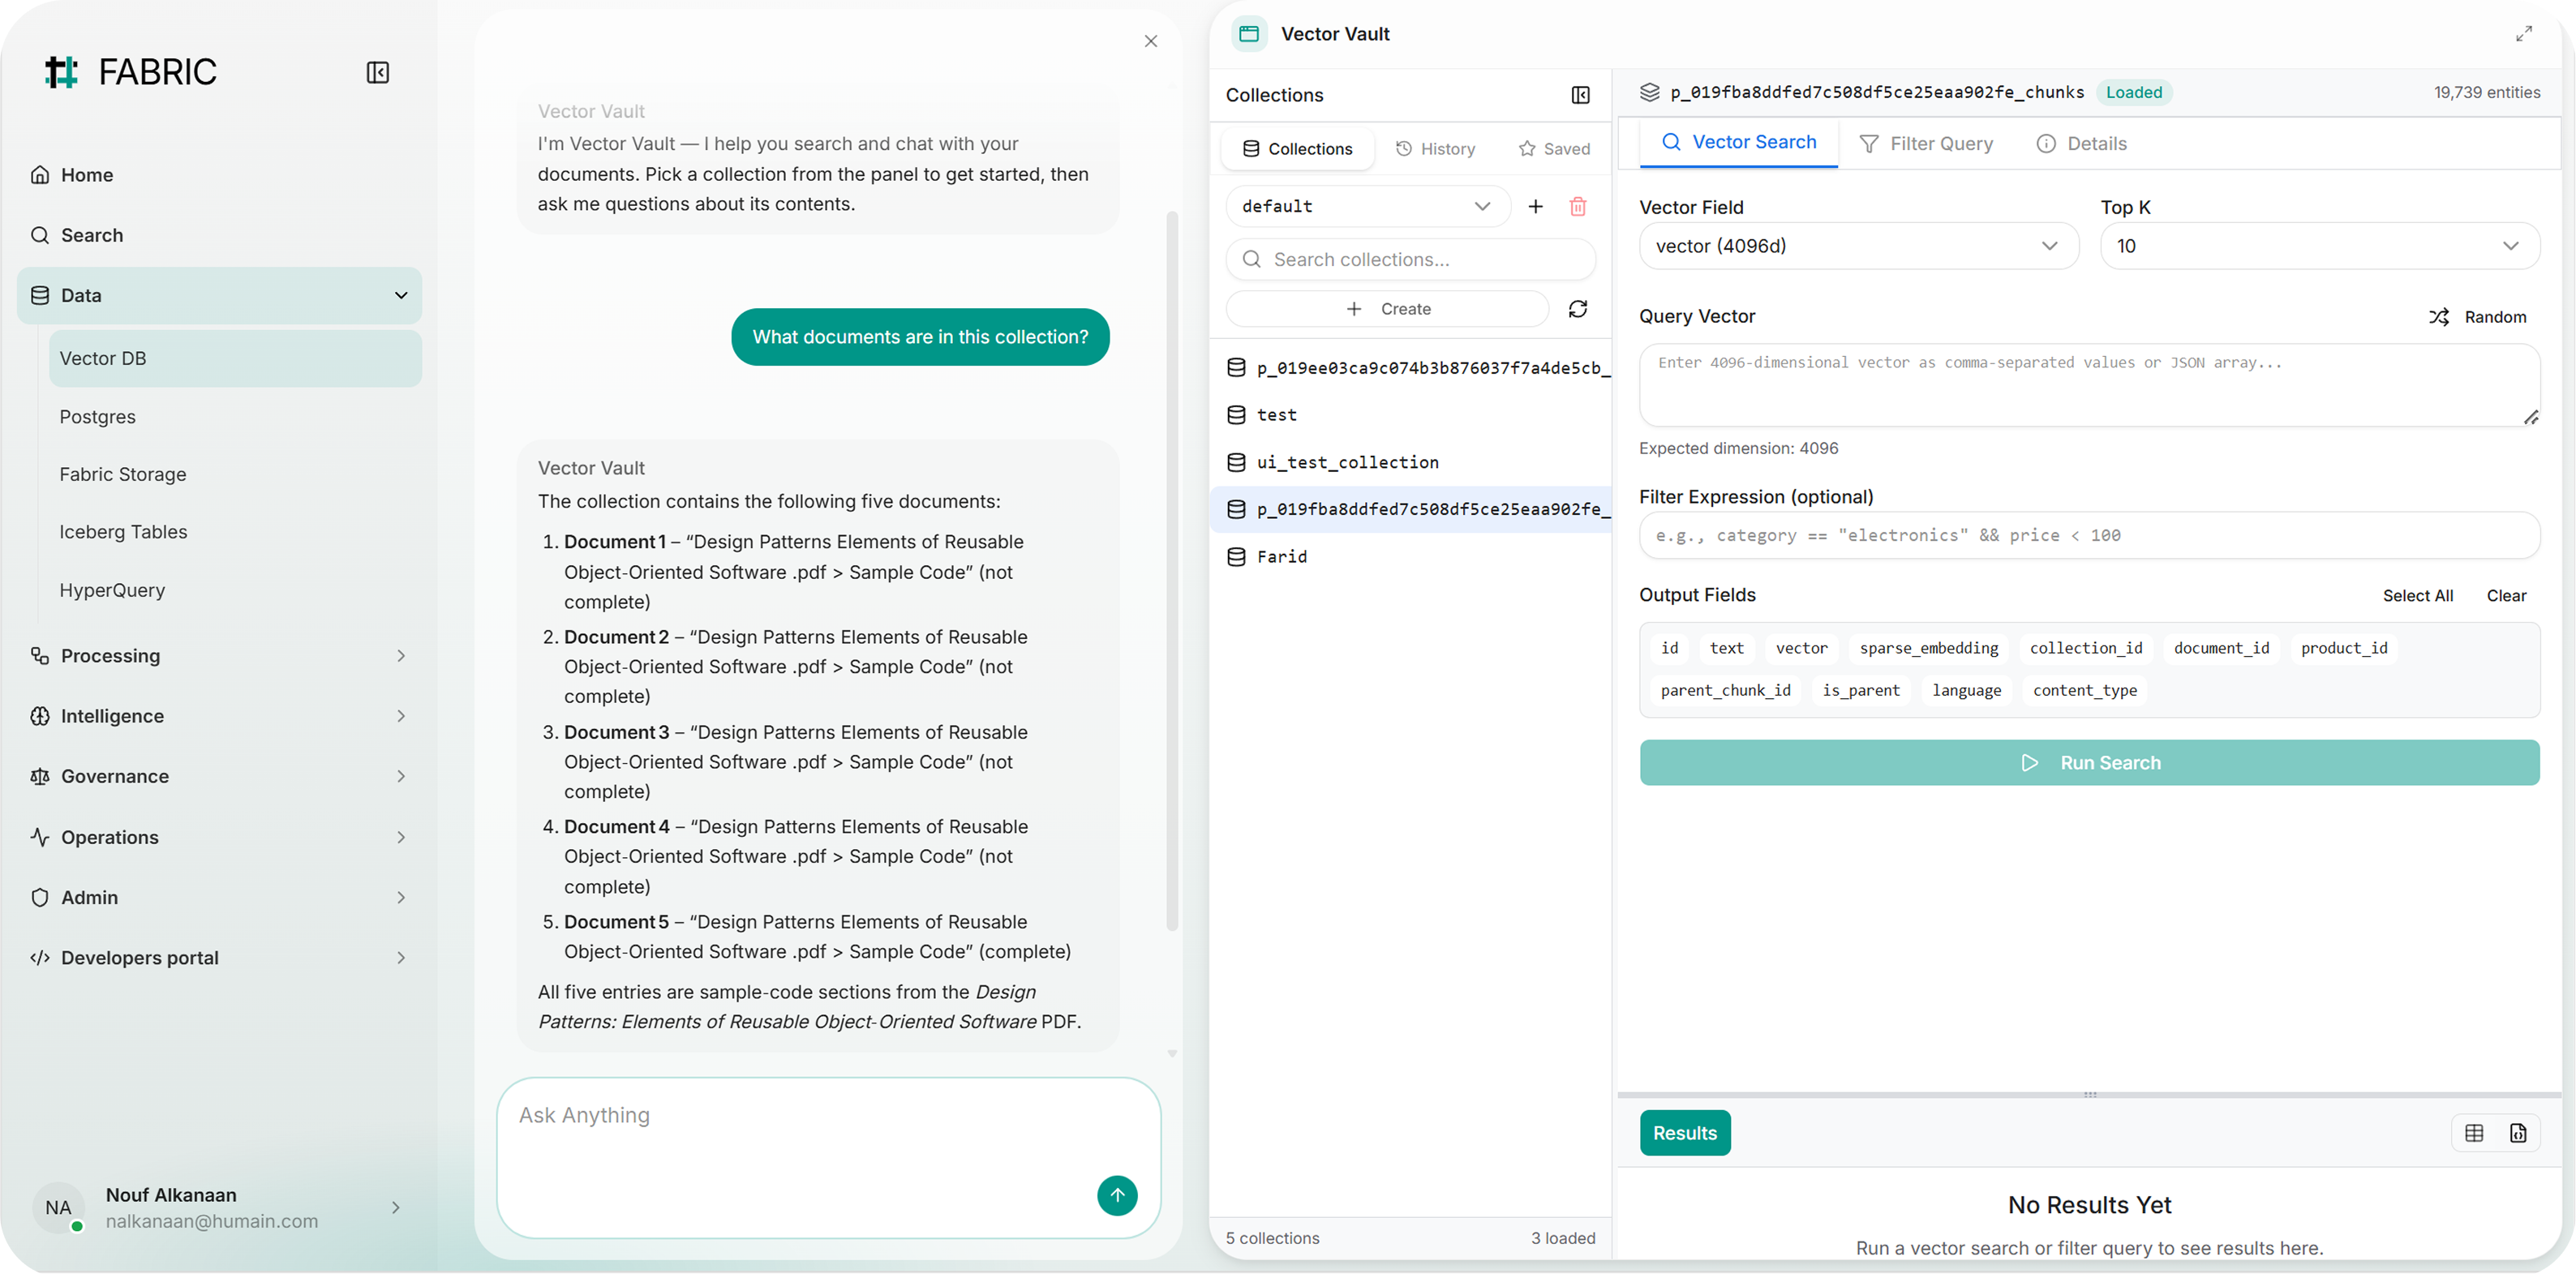
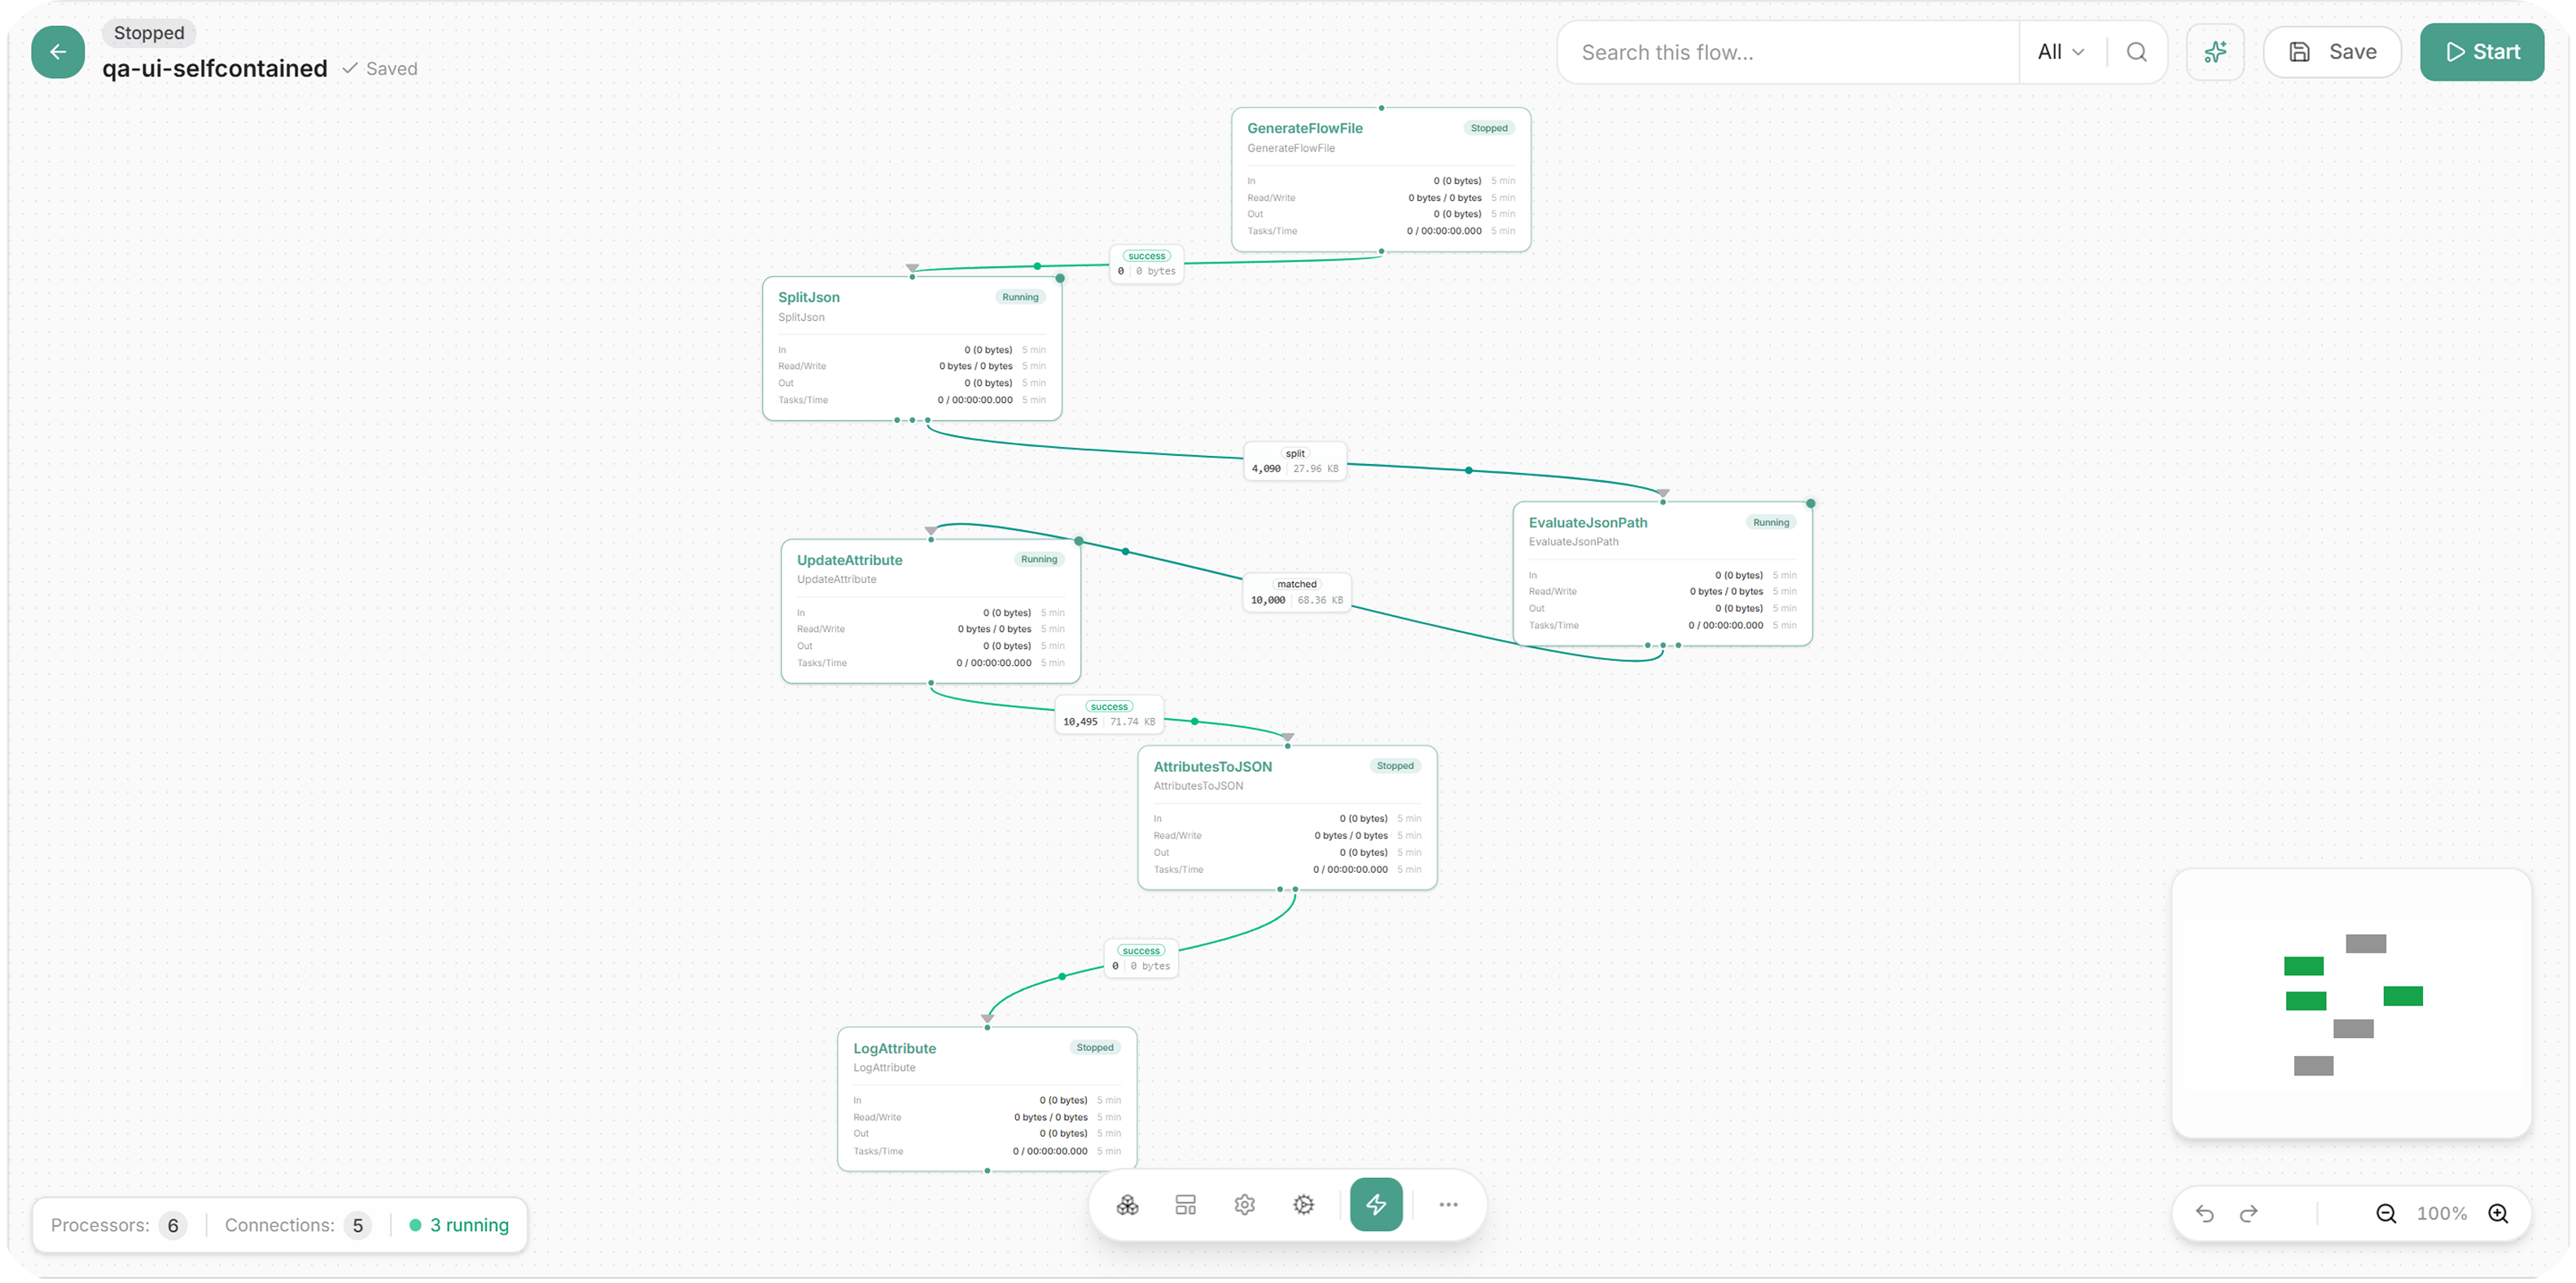
Six core services form the foundation of a governed enterprise data lifecycle.

Any source, any format, any time: real-time updates, scheduled uploads, or files from cloud storage. Every source seen, every record tracked

Files, objects, AI-ready datasets, and raw streams in one connected system. AES-256 encrypted from day one, S3-compatible, no rewrites.

Analyze, transform, and explore at any scale: ML dataset prep, multi-step pipelines, or billions of records in real time. Less plumbing, more insight.

Every pipeline in harmony, every dependency resolved. Runs are tracked, versioned, and reproducible, so you can replay, audit, and compare.

Scattered, siloed data gathered into one reliable vault.

Your single source of truth for every data asset. Tables, topics, and pipelines auto-discovered across connected systems, with AI to get you there faster.
Each layer is built from specialized components across data, processing, and governance.
Store and search billions of high-dimensional embeddings at millisecond latency, powering semantic search, RAG, and recommendations without infrastructure overhead.
Store structured data, run SQL, manage schemas, save queries, and schedule jobs in one place. Postgres for the richest Fabric-native features, MySQL for wire-protocol compatibility.
S3-compatible storage for unstructured data and files. Buckets are searchable, sized on demand, and encrypted at rest with AES-256 per-organization keys, so your data is cryptographically isolated.
Built for large-scale aggregations and joins over big datasets. Ad-hoc exploration, dashboard backends, and read-heavy queries that run fast without separate infrastructure.
Build pipelines visually, run them at scale. More than 300 prebuilt processors handle real-time and batch transformation with full lineage, drag-and-drop design, and no hidden execution logic.
Orchestration in pure Python, tracked to the run. Schedule multi-step workflows, handle retries automatically and replay any past execution exactly. Every DAG versioned and auditable.
Petabyte-scale Spark on demand. Clusters spin up for the job and disappear when done: no idle compute, no ops overhead, full integration with Fabric lineage and catalog.
Every asset discovered automatically. Tables, pipelines, and topics across every connected system, searchable by name, tag, column, or plain language as soon as they land.
Always know where data has been. Trace any dataset from source to consumption: what transformed it, what depends on it, what breaks if it changes, maintained automatically.
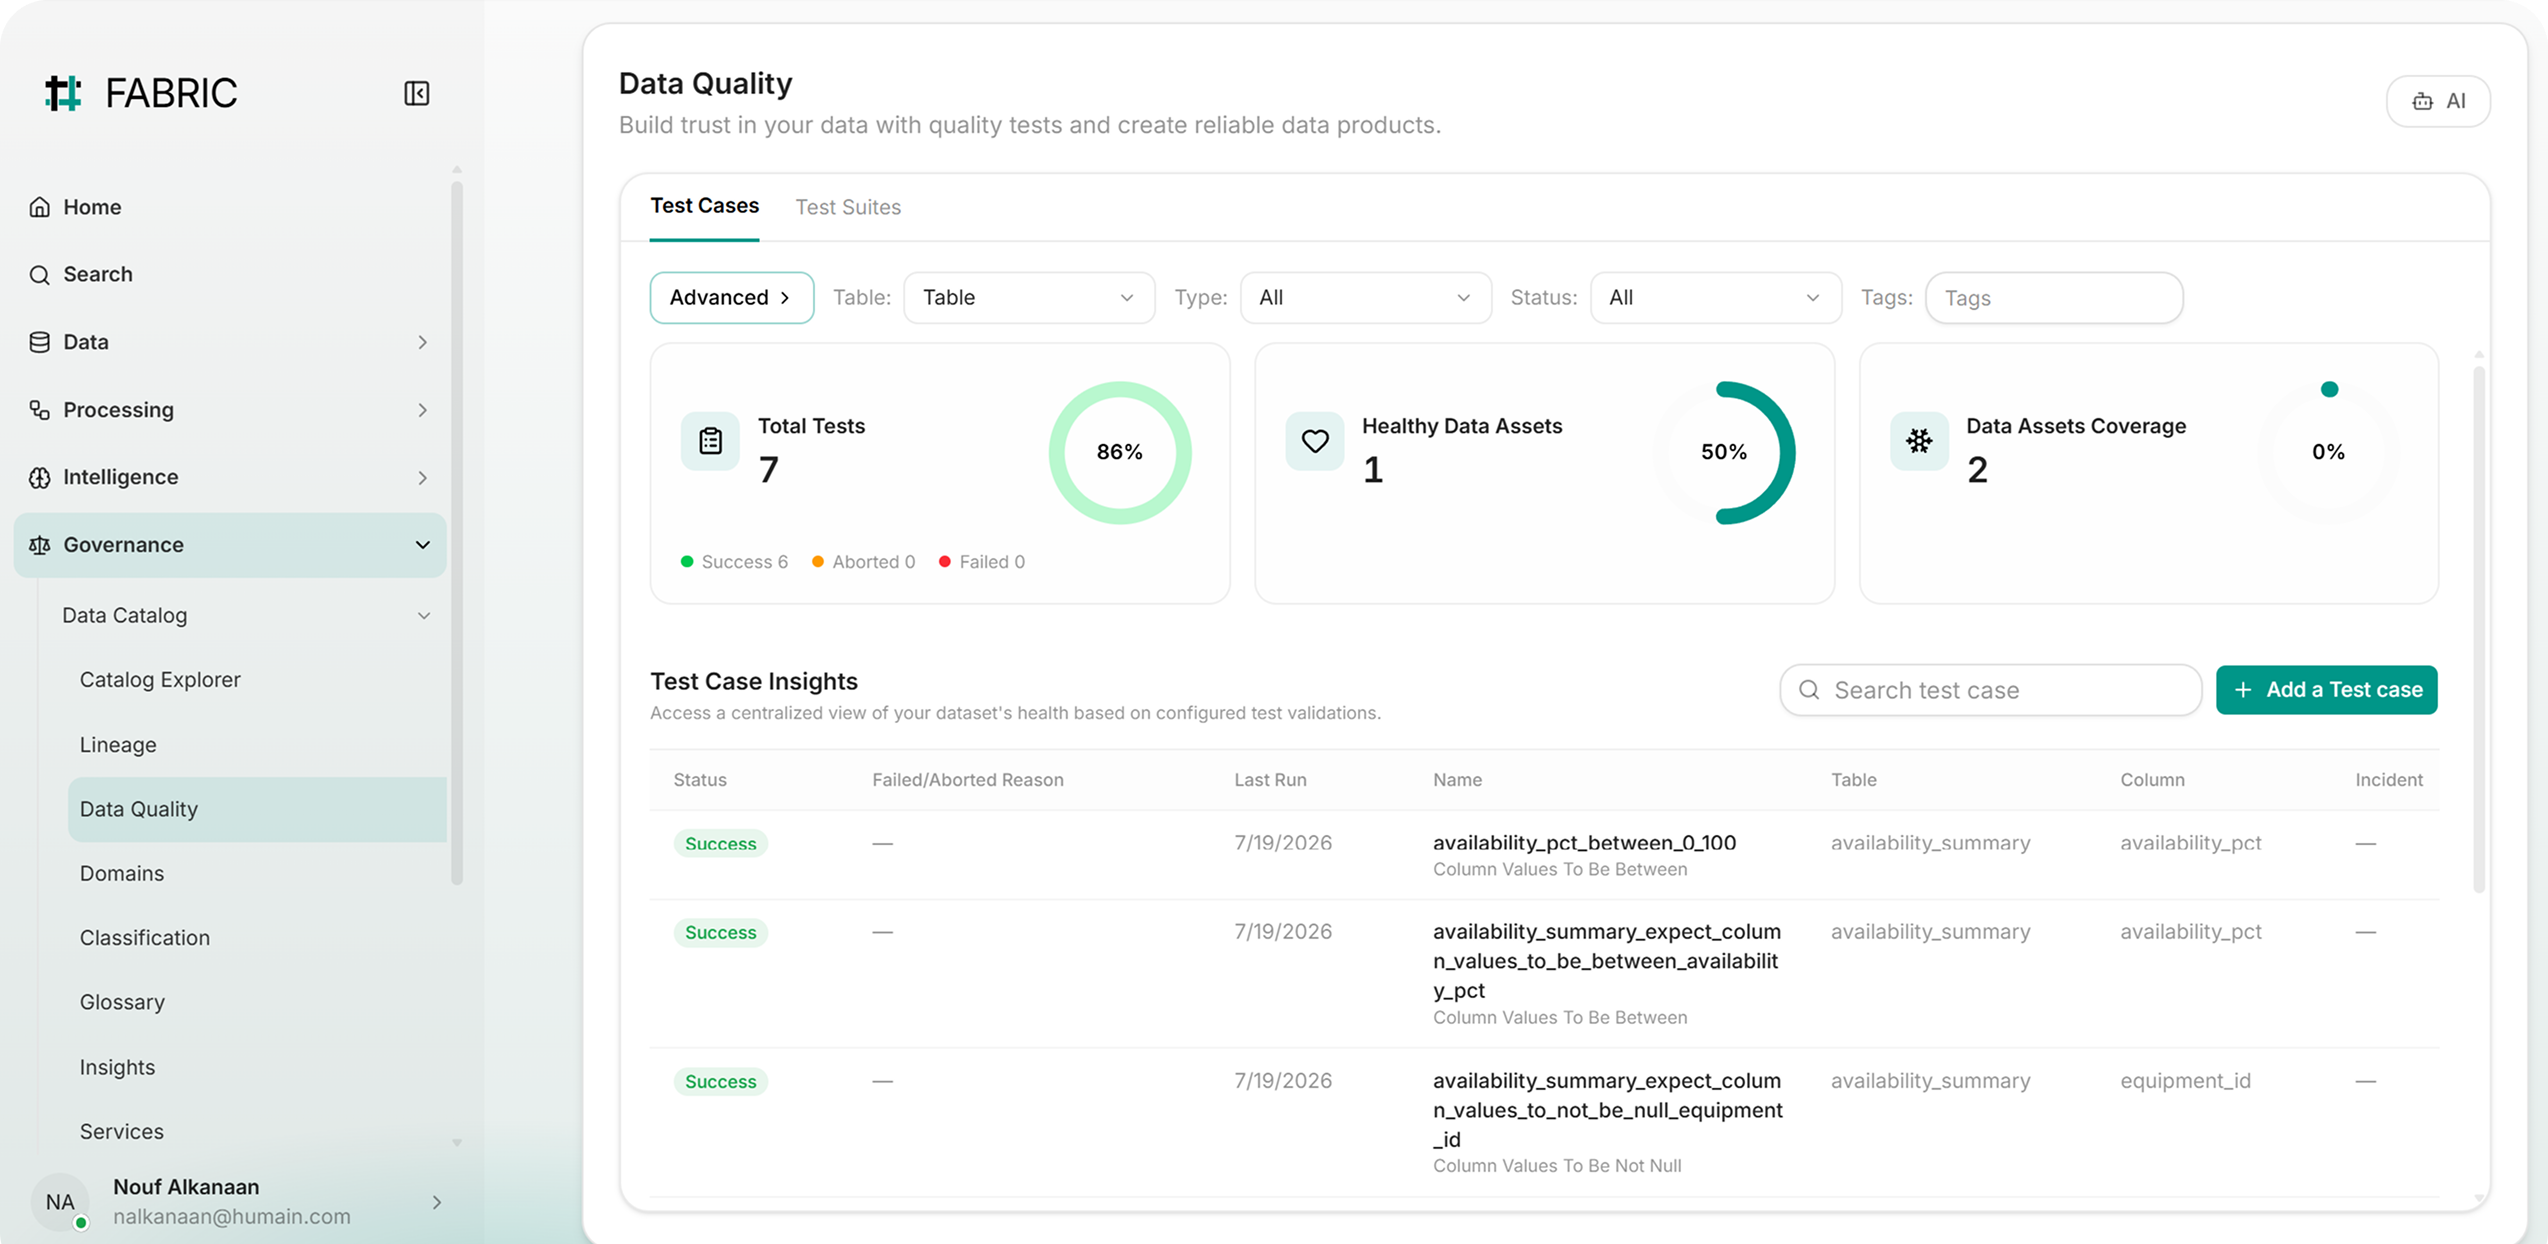
Catch issues before production. Continuous pass and fail checks on every asset, with automatic alerts and root-cause signals, so bad data never silently reaches a model or a report.
Governance in the data, not on top of it. Every asset tagged with sensitivity, domain, and compliance labels at ingest, so access controls and audit trails are automatic.
One definition, within every team. A shared glossary linking technical assets to business terms, so engineers, analysts, and stakeholders speak the same language.
Ask what you need and it gets done, from data queries to storage, databases, and analytics. One platform, every tool, reachable through conversation.
 MCP and
Agents
Model
Context
Tenant
Auth
Audit
Trace
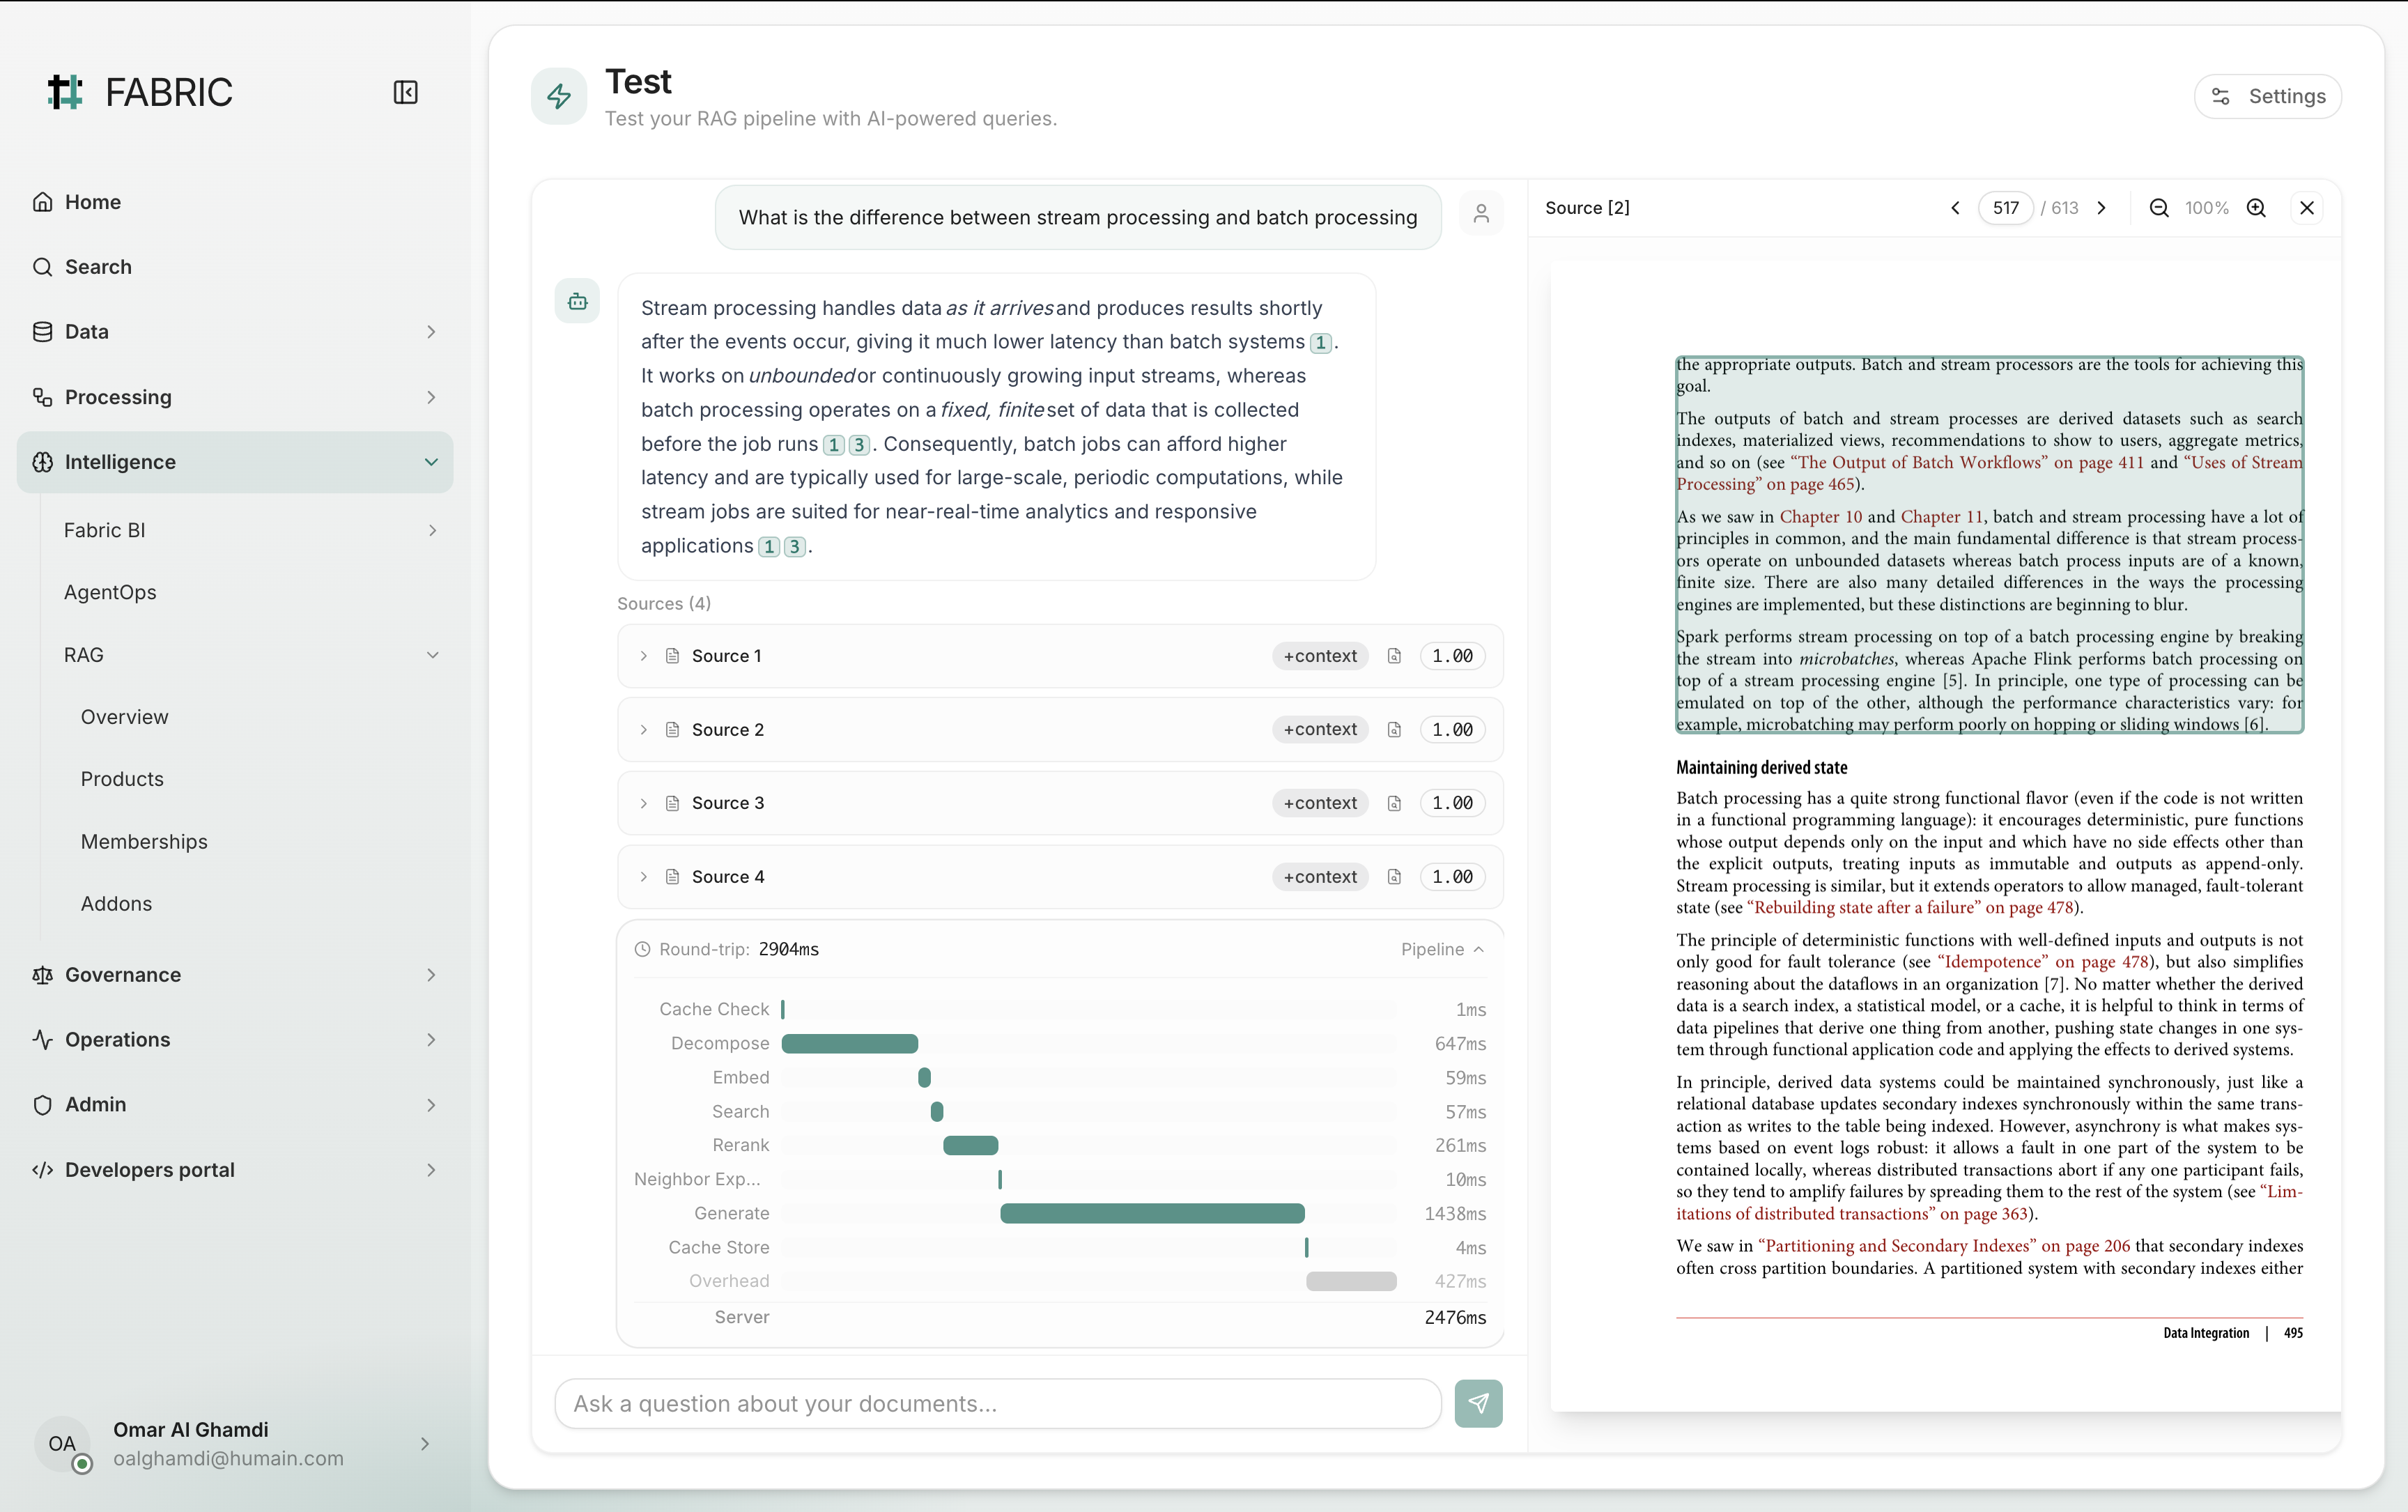
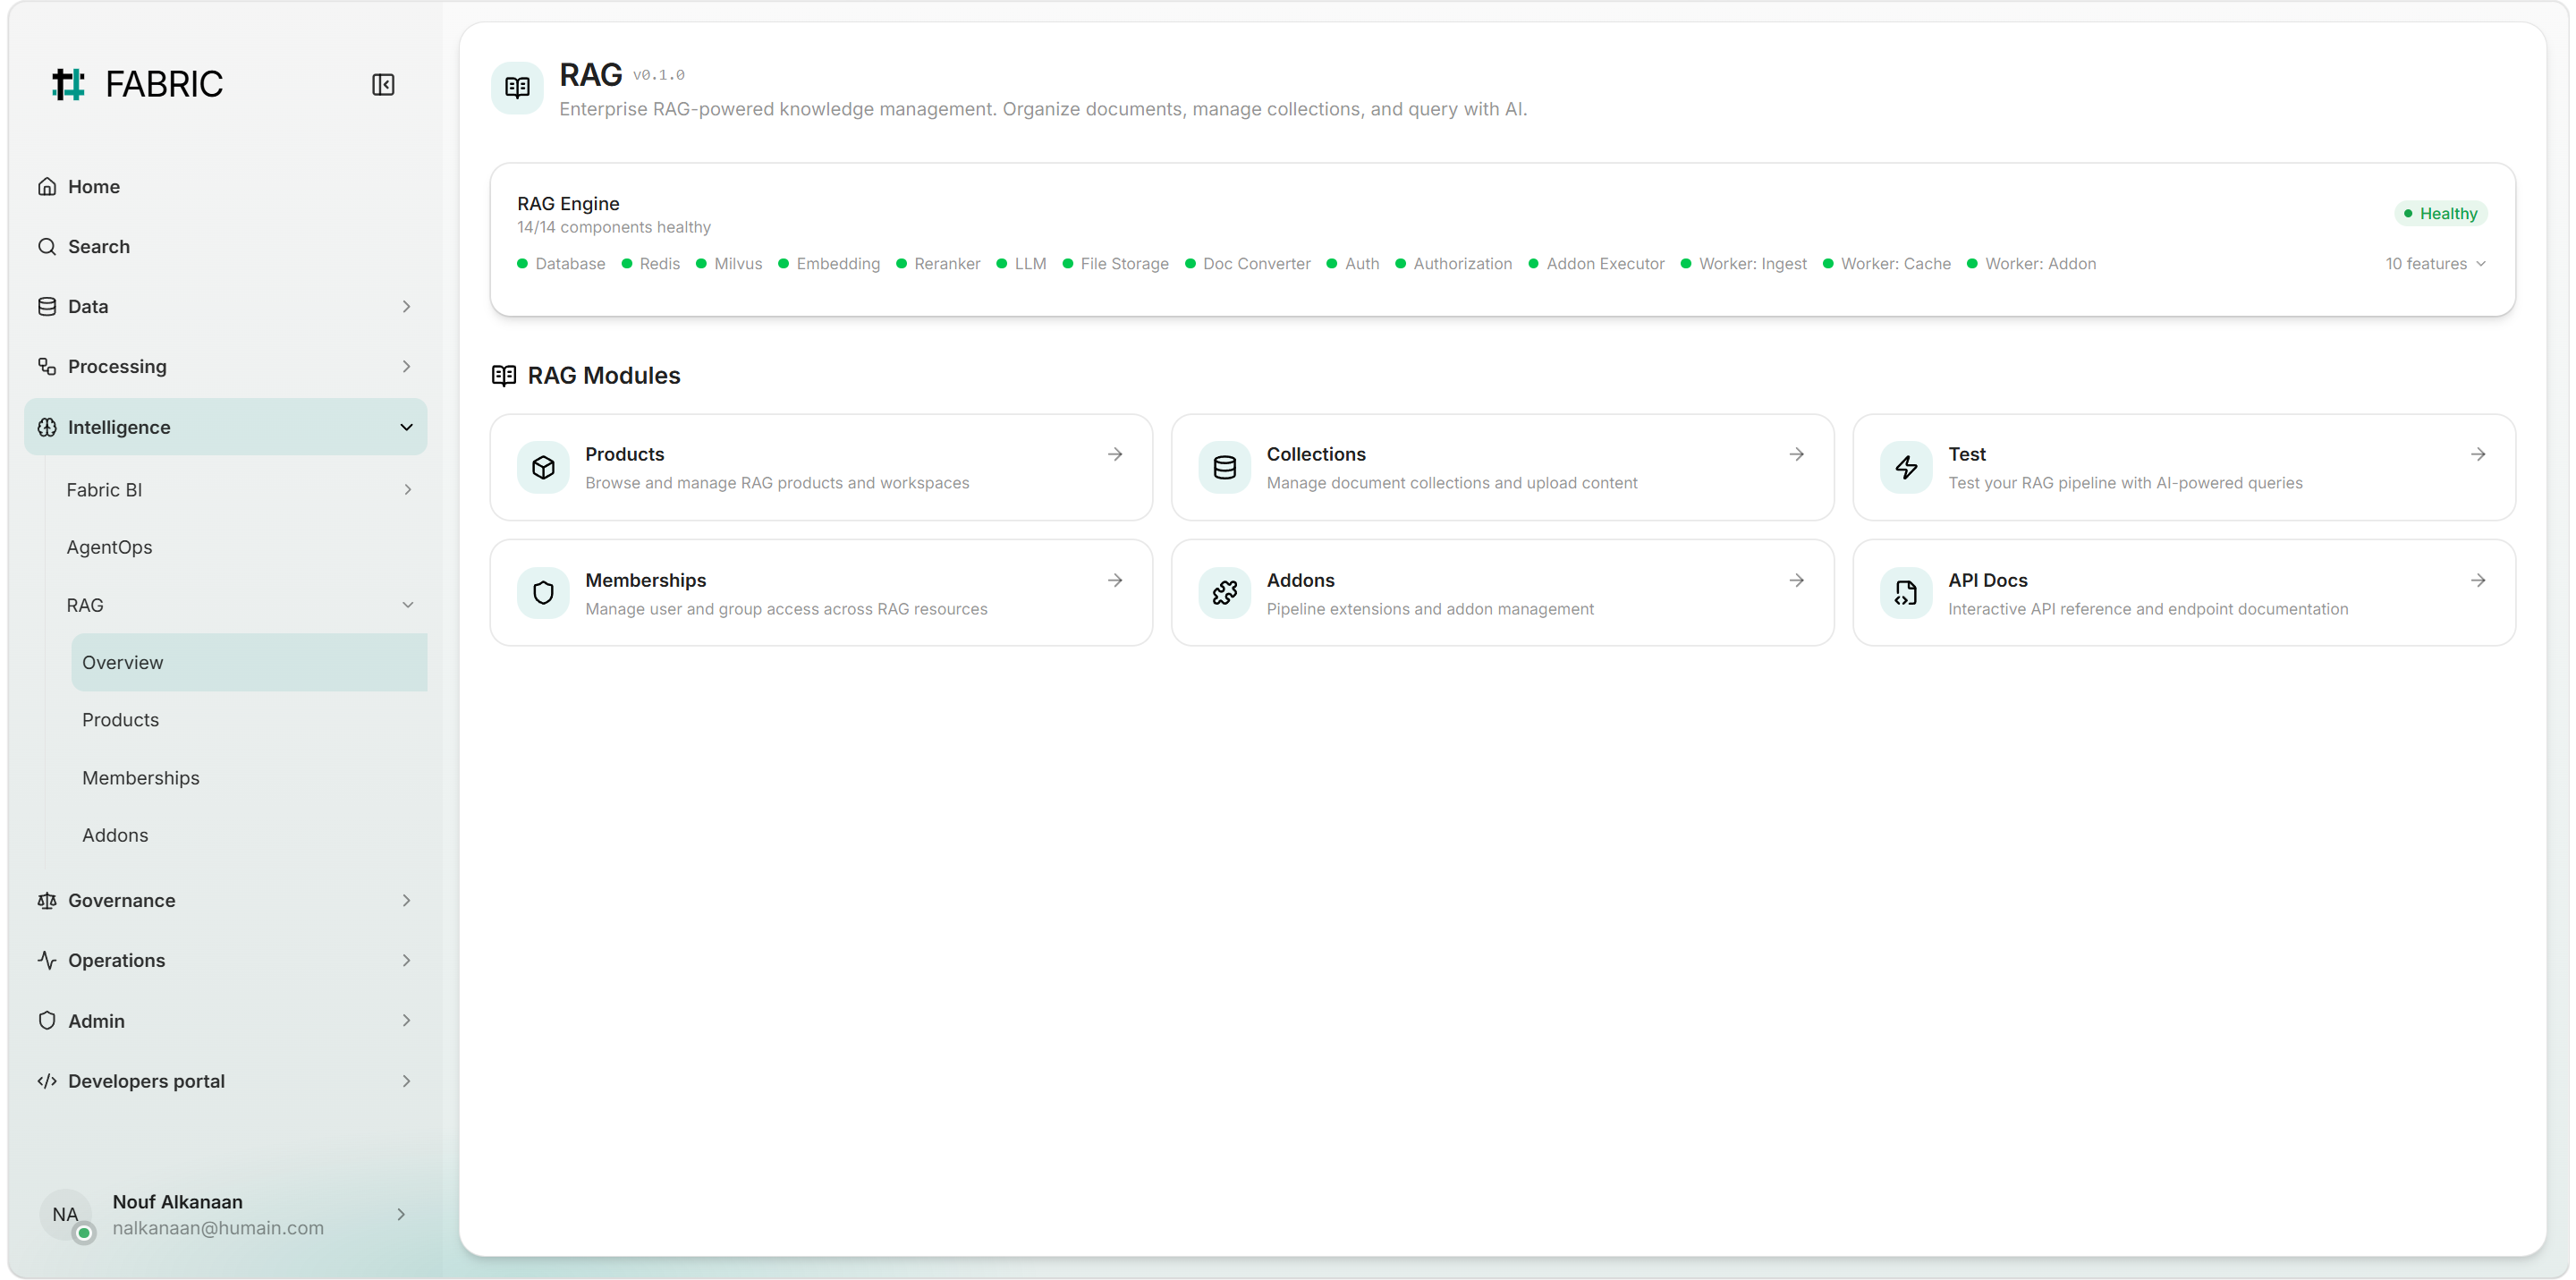
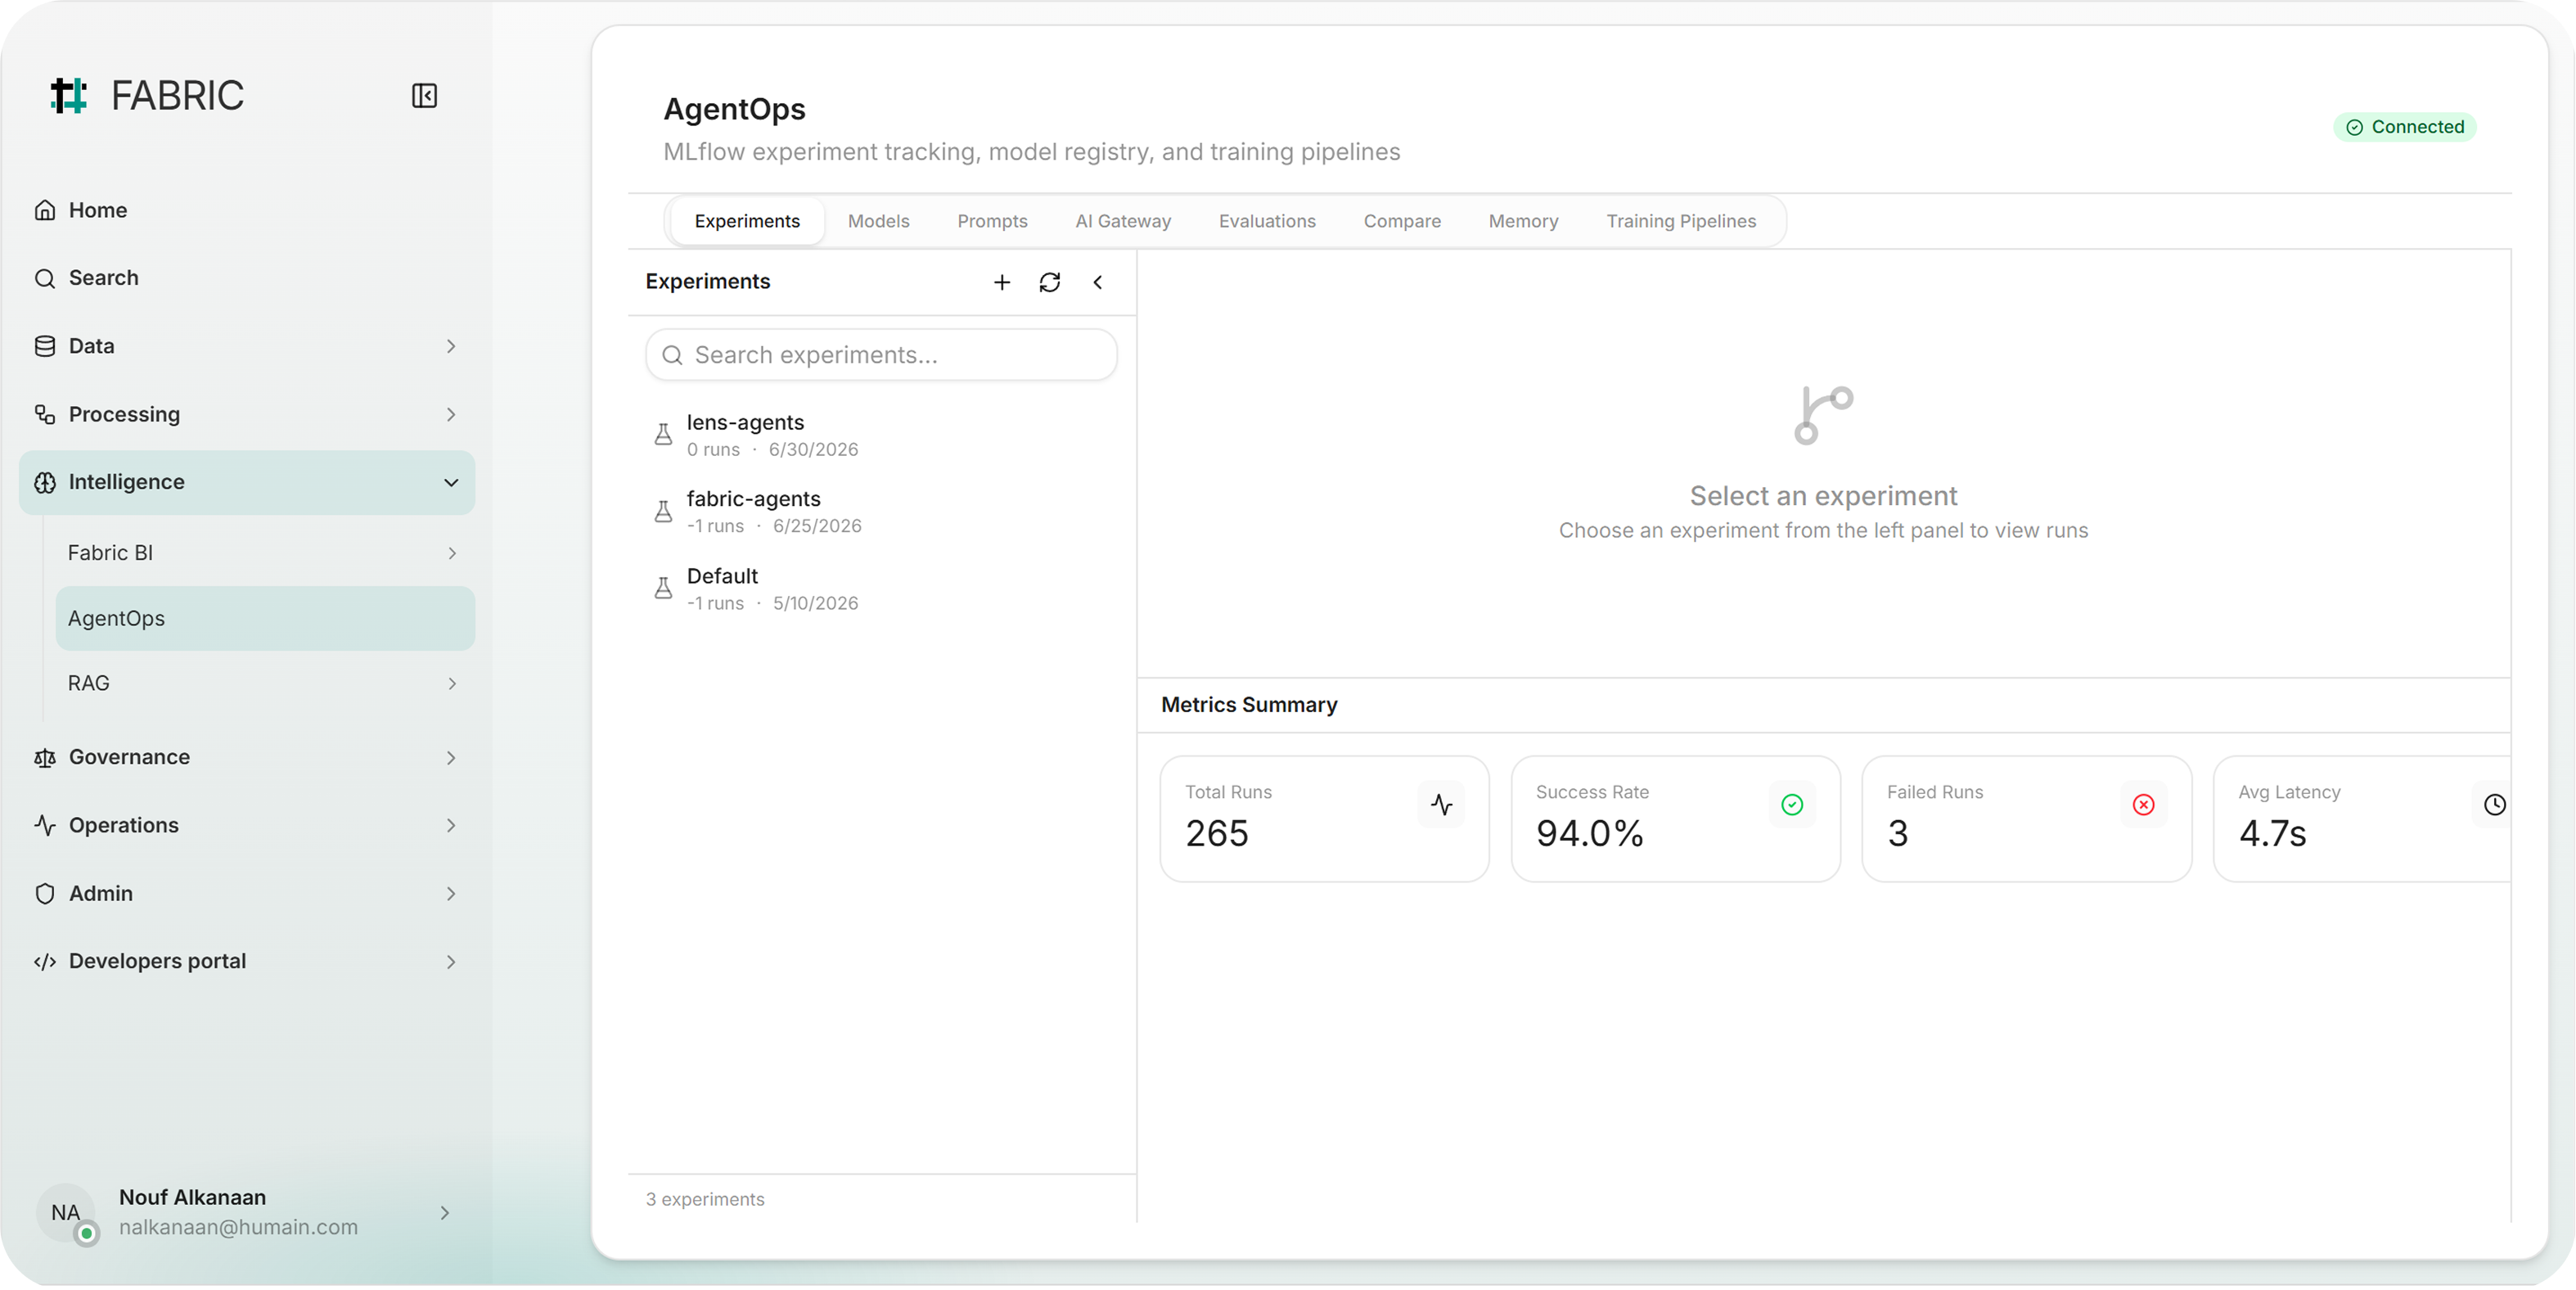
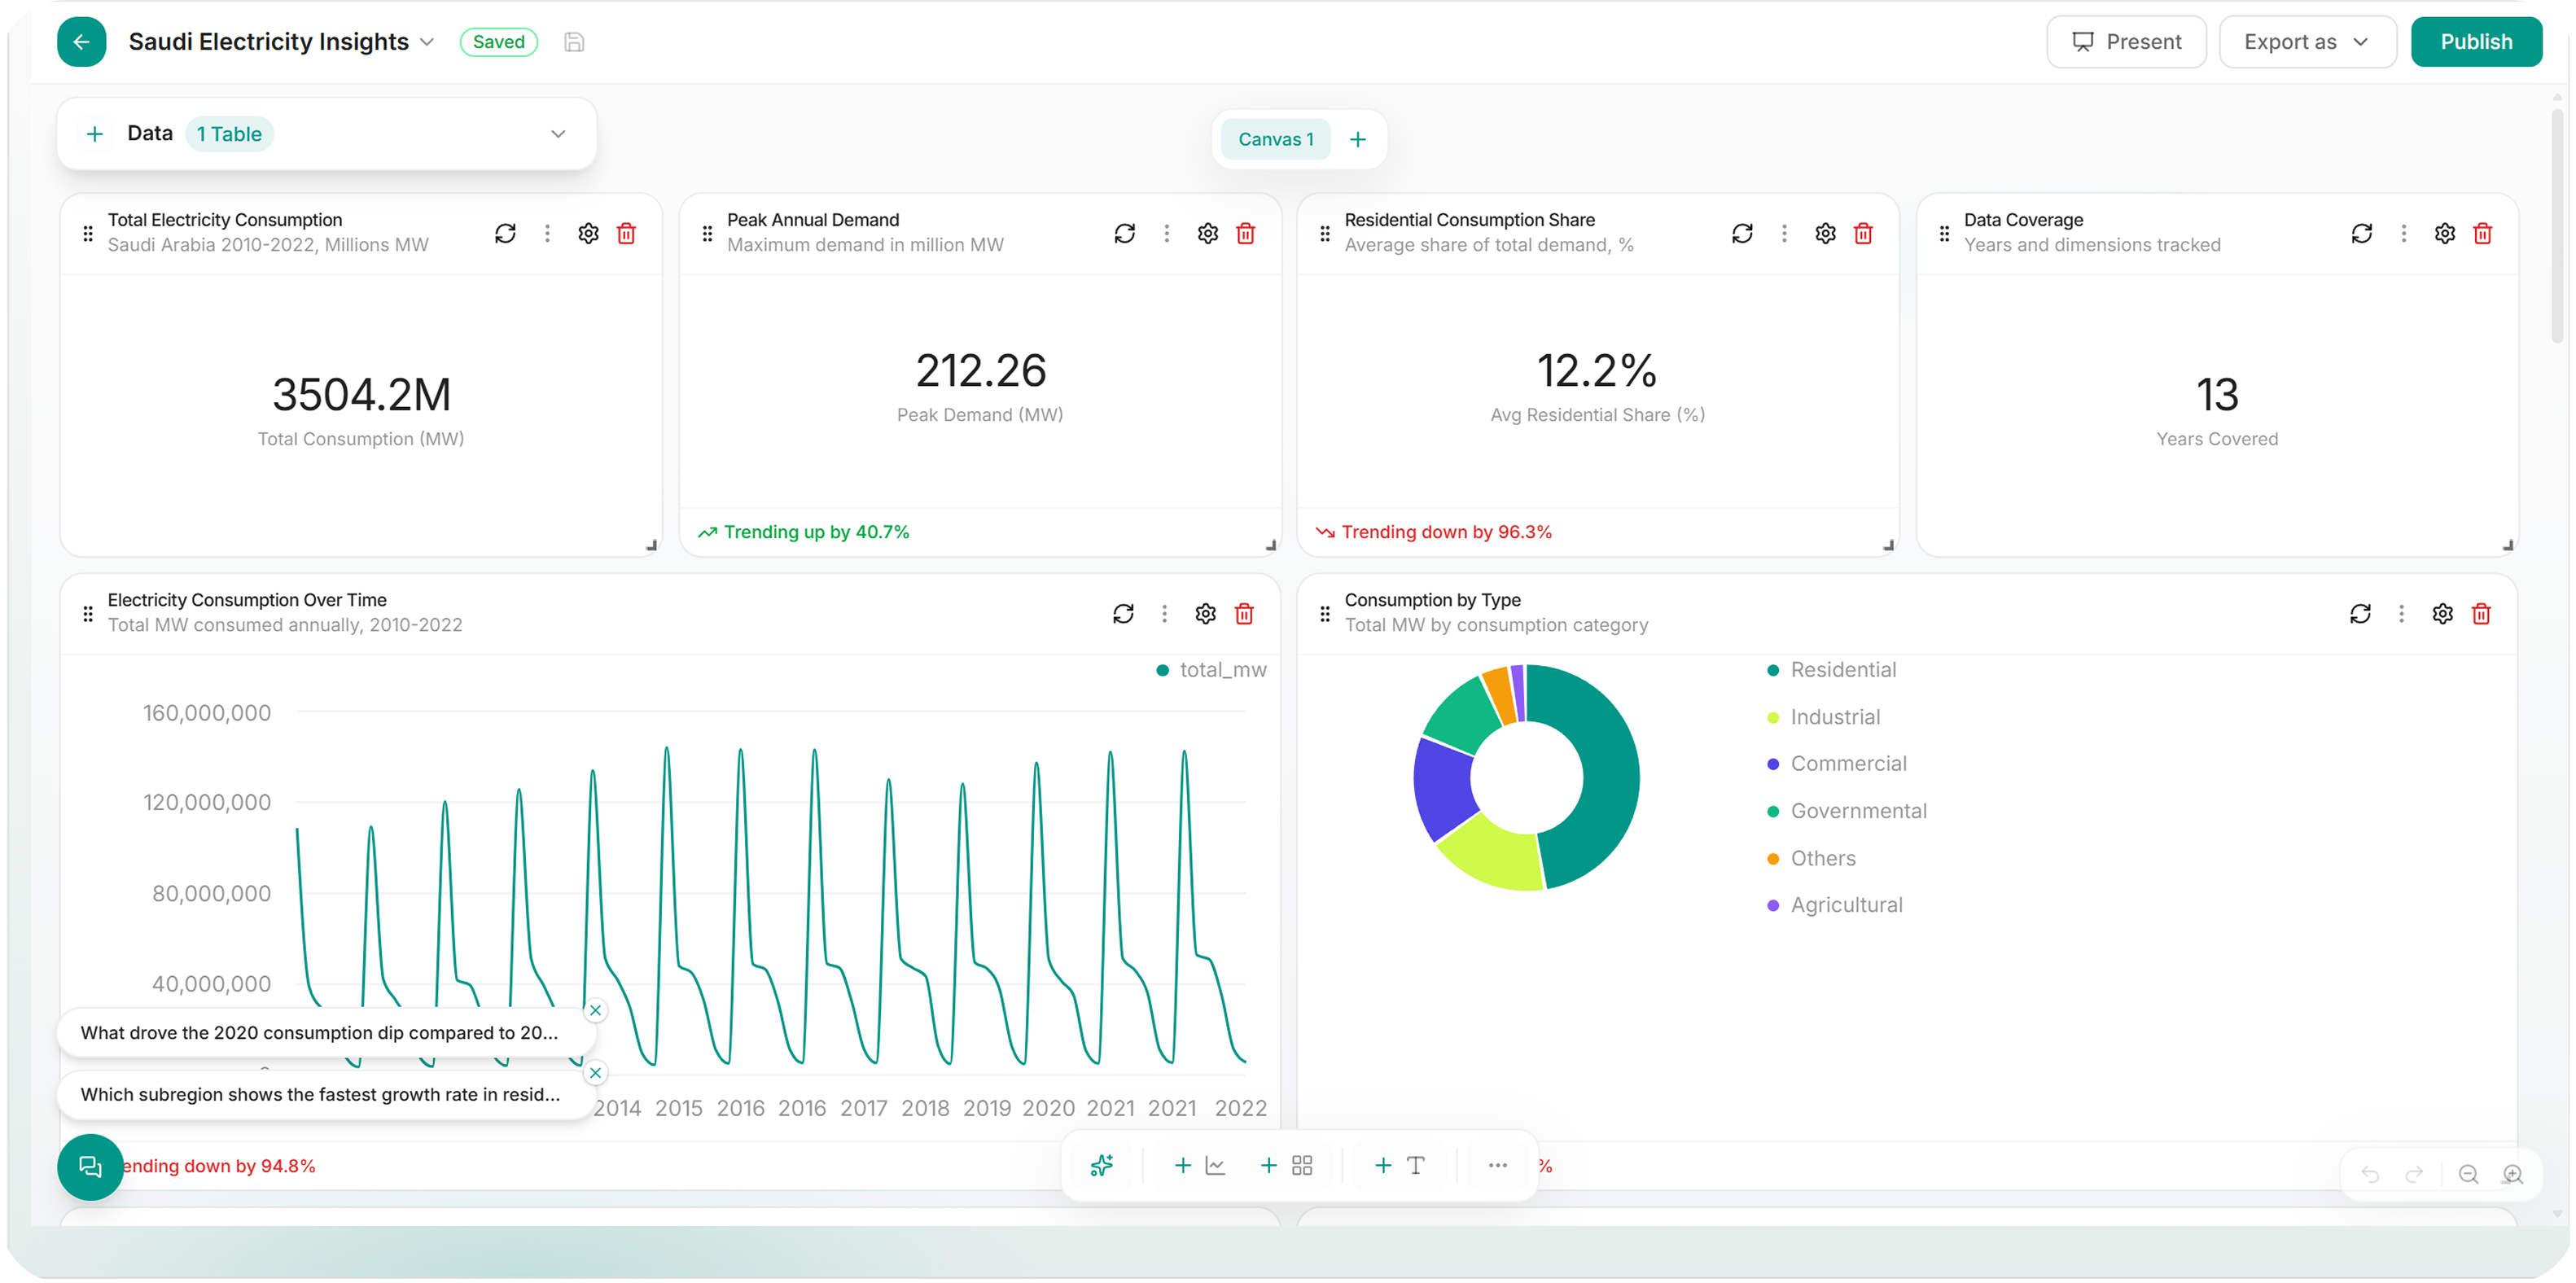
Across the tools and environments teams use to explore, build, retrieve, and monitor AI-powered workflows.

Teams get plain-language answers: what happened, what changed, what was affected, and where to focus next. Due to AI that watches your systems around the clock, detects issues early, and investigates as soon as they appear.

Reads, reasons, and responds: understands intent, pulls the most relevant information across sources, and delivers accurate answers without users needing to know where to look. Every answer traceable.

Integrated notebook environment for data exploration, prototyping, and model development.

A form-building surface with form status, creation, and AI-assisted building.

Every team gets a space to turn data into interactive dashboards: drag, drop, explore, share. Or describe what you need and the agent builds it, choosing charts and connecting to live data in seconds.

Connects to databases, APIs, files, and streams, profiles the schema automatically, and lands clean, governed data into Fabric continuously, without hand-written pipelines.

Maps source schemas to targets, plans the cut-over, validates row counts and integrity, and runs in supervised steps, so teams move fast with full traceability.

One prompt, the whole platform pitches in: your data, your tools, your context. No tabs to hop, no SQL to remember, no prompt-engineering degree required.
Native Arabic expertise, outcome-driven delivery. One integrated team across every phase — from discovery and readiness assessment to live production — so nothing falls between vendors and every result is accountable.
Organizations come to us at very different stages. We meet you at yours, and take you to the next.
For organizations early on, who need to find where AI delivers real ROI and whether their data is ready.
For organizations standing up their initial production use cases, who need quality data and engineering muscle to ship something that works.
For organizations moving from pilot to production at scale, where data quality, annotation volume, and governance have to keep pace.
For organizations with AI live in production, who need continuous evaluation, governance, and managed operations to sustain it.
From AI discovery and readiness assessment to sustained operations: one integrated team, end to end, zero hand-offs.
It begins with the AI Readiness Assessment: we map your data, systems, and goals to surface the AI use cases with the highest ROI — then turn the winners into a 90-day action plan and 12-month roadmap.
We define a data vision tied to your business outcomes, design the operating model and stewardship roles, and align senior stakeholders — so data has owners, not just ambitions.
Audit your data posture, define ownership, configure PII classification, and map lineage across critical pipelines. Our QuickStart turns scattered policies into an operating model in six weeks.
Forward Deployed Engineering: HUMAIN Fabric engineers working inside your operating rhythm, accountable for getting AI into production. A premium tier for national-scale and mission-critical programs.
Independent evaluation across performance, safety, alignment, cultural fit, and readiness. Custom benchmarks, bias testing, and third-party validation that ends in a defensible recommendation.
Multi-tier annotation across text, image, audio, and multimodal data — with native Arabic and MENA cultural review built in, not bolted on.
Annotation pipelines, quality monitoring, and scheduled evaluations running on SLA — so your model keeps improving without 20 new hires. No hand-off. We stay on.
Everything your AI needs to move from data to action
Get it Now